Skip to content

Blog

Kubernetes v1.36: Migrate Off ingress-nginx Before You Read the Rest

Banner image Banner image

Here's the thing about ingress-nginx: it's everywhere, it's boring, and it works. That's exactly why this is hard. The CNCF moved it to end-of-life in March 2026. The sig-network team is no longer cutting releases. There will be no security patches. And if you've been running it quietly in the background — which most of us have — it's been accumulating unpatched CVEs since then with nobody upstream doing anything about it. The project repository still exists. The community hasn't vanished overnight. But the organised maintenance is gone, and that means your ingress layer is now in the same category as anything else you'd describe as "unsupported dependency." That's not a comfortable place for traffic handling.

Look, I know migration from ingress-nginx sounds like a weekend you don't have. It's not usually a single Helm value change. But the risk calculus has shifted fundamentally. Before March 2026, a known CVE in ingress-nginx meant "there'll be a patch release in a few days." After March 2026, it means "you're carrying this forever unless you move." That's a different situation, and it deserves a different response than "we'll get to it."

The good news — and there's genuinely good news in v1.36 — is that once you've dealt with the ingress situation, this is a solid release. User Namespaces goes GA. SELinux volume mounting goes GA. DRA device taints graduate to beta. If you're running multi-tenant clusters or SELinux-enforcing nodes, there are real operational wins here. But sort the ingress-nginx situation first.

OpenClaw 2026.4 Release: What Changed

Banner image Banner image

Something I didn't expect: the most useful thing in OpenClaw 2026.4 isn't one of the headline features. It's a fix to a problem that was driving me quietly mad.

My OpenClaw instance runs across two contexts — a work Slack and a personal WhatsApp. After a few weeks, the memory model had blended them into a single soup. It knew about both my team's sprint retrospective and a conversation with my family about where to go on holiday, and every now and then something from one context would surface in the other in a way that felt off. Not wrong, exactly. Just.. the wrong kind of thing to remember for this conversation.

The 2026.4 memory filters fix that. You can now scope what each channel remembers and reads, which sounds like a small thing until you've run an AI assistant across mixed personal and professional channels for a few months.

That said, there's more here than memory: four new stable channels, meaningful run-steering improvements, and the groundwork for Bedrock and NVIDIA inference backends landing in 2026.5. Here's what actually changed and what's worth configuring before you upgrade.

AI Convention Files in Practice: Azure DevOps

Banner image Banner image

AI Convention Files in Practice: Azure DevOps

The taxonomy post covered every AI convention file type — AGENTS.md, SKILL.md, .prompt.md, and the rest. This post puts them to work with Azure DevOps.

Every example below uses real WIQL queries, references actual ADO fields, and follows patterns extracted from a production agents.md that populates sprint review decks from ADO work items.

ADO automation in numbers

Teams running these patterns typically complete sprint review prep in under 5 minutes — compared to 30-60 minutes of manual ADO querying and copy-pasting. The key metric: 38 requests, categorised, calculated, and dropped into slides without touching a spreadsheet.


How agents talk to Azure DevOps

An AGENTS.md file defines what the agent should do. An MCP server provides the runtime connection to ADO. The agent reads the workflow from AGENTS.md, then calls the ADO MCP server to execute WIQL queries and retrieve work item data.

ADO agents workflow ADO agents workflow

The ADO MCP server exposes tools such as wiql_query, get_work_item, and list_iterations. The agent never needs raw HTTP calls — it invokes these tools through the MCP protocol, and the server handles authentication, pagination, and field mapping.

Apply this: scope MCP tools to what agents actually need

The ADO MCP server loads all domain tools by default. Use the -d flag to restrict to core, work, and work-items. Fewer tools means less cognitive overhead for the agent and a smaller permission footprint — especially important when agents run in CI contexts.


What gets automated (and what does not)

Not everything in a sprint review can come from a query. Migrations, new platform capabilities, infrastructure redesigns — that work spans multiple sprints with epics and milestones, and reporting on it is narrative. What shipped, what slipped, what the team learnt. An agent cannot write that.

Operational work is different. Access provisioning, pipeline fixes, Azure resource configuration, troubleshooting — these arrive as Requests, get resolved, and pile up. Individually they are routine. In aggregate they tell a story: which categories dominate, how resolution times trend, whether the same teams keep submitting. That is numbers, and numbers come from WIQL.

The agents in this post target operational work. They query ADO, run the calculations, and drop the results into a Marp sprint review deck. Project slides stay in the same deck as fixed templates — same layout every sprint, content filled in by hand.

In ADO terms: operations work typically lives under a shared Area Path (like Engineering\Platform Consulting) with a Request work item type. Projects live under their own Area Paths with Feature, User Story, and Task types.

The mixed work-type tell

If your Area Path contains both Request items and project Feature/Story items, WIQL queries will silently include project work in operational metrics unless you filter by [System.WorkItemType] = 'Request' explicitly. Validate your query results against a manual count before trusting the numbers in your first sprint review run.


Use case 1: Sprint review deck automation

A single agents.md file orchestrates multiple agents that query ADO, categorise completed work, calculate metrics, and update a Marp presentation deck — no manual data gathering needed.

The agent definition

## Agent: Update Request Metrics Summary

Task: Update deck.md with request metrics from the current sprint

Steps:
1. Query ADO for all Requests in area path from last 2 weeks
2. Calculate metrics:
   - Count by category (Access, Infrastructure, Pipeline, Azure Config)
   - Average resolution time (ClosedDate - CreatedDate)
   - SLA compliance % (resolved within 24 hours)
   - Unique requestors and repeat request %
3. Show calculated metrics to the user
4. Ask: "Update deck.md with these metrics? (yes/no)"
5. If approved, update the metrics table and key insights
6. Report what was updated

The WIQL query

SELECT [System.Id], [System.Title], [System.Tags],
       [System.CreatedDate], [System.ClosedDate], [System.CreatedBy]
FROM WorkItems
WHERE [System.WorkItemType] = 'Request'
  AND [System.AreaPath] = @AreaPath
  AND [System.State] = 'Done'
  AND [System.ClosedDate] >= @StartDate
  AND DATEDIFF(day, [System.ClosedDate], GETDATE()) <= 14
ORDER BY [System.ClosedDate] DESC

@AreaPath is defined in the agent configuration — typically in the agents.md header or passed as a parameter when the agent runs. This keeps the queries portable across teams and organisations.

What the agent produces

The agent calculates metrics from the query results and updates the deck:

Category Count %
Access & Permissions 10 26%
Pipeline & CI/CD 8 21%
Infrastructure Provisioning 7 18%
Environment Configuration 5 13%
Secrets & Certificates 4 10%
Troubleshooting 3 8%
Other 1 3%

Key metrics: 38 requests completed, 1.4 day average resolution, 89% SLA compliance.

The human confirms before any file is written. The agent explains what changed and suggests running make diagrams to regenerate presentation PNGs.


Use case 2: Requestor pattern analysis

A companion agent analyses who is requesting work, identifying top requesting teams and spotting patterns that suggest automation opportunities.

## Agent: Update Requestor Patterns

Steps:
1. Query ADO for all Requests from last 2 weeks
2. Extract requesting team from Custom.RequestedTeamName
3. Group by team and count requests
4. Get top 5 requesting teams
5. For each team, identify:
   - Most common request types
   - Repetitive patterns (automation candidates)
6. Update the PlantUML bar chart with actual data
SELECT [System.Id], [System.Title], [System.CreatedBy],
       [System.Tags], [Custom.RequestedTeamName]
FROM WorkItems
WHERE [System.WorkItemType] = 'Request'
  AND [System.AreaPath] = @AreaPath
  AND [System.CreatedDate] >= @StartDate
  AND DATEDIFF(day, [System.CreatedDate], GETDATE()) <= 14

The agent updates a PlantUML bar chart data array directly — no placeholder values, just real numbers from ADO.

Repetition patterns are your automation backlog

When one team accounts for 30%+ of requests and their top category is always the same (usually access provisioning or environment config), that is a self-service candidate. Run this agent for three sprints before drawing conclusions — one sprint of high volume might just be a project launch.


Use case 3: Sprint-over-sprint trend comparison

This agent compares the current sprint against the previous one to identify improvements and regressions.

## Agent: Key Insights & Improvements

Steps:
1. Query current sprint (last 2 weeks) AND previous sprint (2-4 weeks ago)
2. Compare:
   - Average resolution time change
   - SLA compliance change
   - Repeat request pattern change
   - Volume by category trends
3. Identify positive trends (with percentages)
4. Identify areas for improvement
5. Suggest specific, data-driven actions
6. Update the Key Insights slide

The previous sprint query:

SELECT [System.Id], [System.Title], [System.Tags],
       [System.CreatedDate], [System.ClosedDate]
FROM WorkItems
WHERE [System.WorkItemType] = 'Request'
  AND [System.AreaPath] = @AreaPath
  AND [System.State] = 'Done'
  AND [System.ClosedDate] >= @PreviousStartDate
  AND DATEDIFF(day, [System.ClosedDate], @StartDate) <= 14

The agent produces data-driven insights: "Resolution time improved 18% (1.5 days → 1.2 days). SLA compliance up from 85% to 91%. Infrastructure Setup requests increased 40% — consider self-service template."


Use case 4: Release checklist with ADO gates

A SKILL.md that verifies all release criteria are met by querying ADO boards and pipelines.

---
name: ado-release-checklist
description: Verify release readiness using ADO pipeline and board data
argument-hint: Provide the release version number
---
# ADO Release Checklist

1. Query ADO for open bugs with priority 1-2 in the release scope
2. Check pipeline status for the release branch
3. Verify all test plans have passed
4. Confirm no blocked work items remain
5. Check that release notes work item is marked Done
6. Report pass/fail for each gate
-- Open blockers check
SELECT [System.Id], [System.Title], [System.State]
FROM WorkItems
WHERE [System.WorkItemType] IN ('Bug', 'Issue')
  AND [Microsoft.VSTS.Common.Priority] <= 2
  AND [System.State] <> 'Closed'
  AND [System.IterationPath] = @ReleasePath

Use case 5: SLO compliance report

A prompt that generates an SLO report from ADO data, suitable for weekly stakeholder updates.

---
description: Generate SLO compliance report from ADO request data
agent: agent
tools: ['search', 'editFiles']
---
Query the last 30 days of Request work items from ADO.
Calculate resolution time percentiles (p50, p90, p99).
Compare against SLO targets:
- p50 < 4 hours
- p90 < 24 hours
- p99 < 72 hours
Generate a markdown table and trend summary.

Use case 6: Incident runbook population

An agent that pulls recent incident data from ADO and updates the team's runbook with resolution patterns.

## Agent: Incident Runbook Updater

Steps:
1. Query ADO for Incidents closed in the last 30 days
2. Group by root cause category
3. For each category with 2+ incidents:
   - Extract common resolution steps from work item descriptions
   - Identify detection patterns (how was it found?)
   - Note mean time to resolution
4. Update the runbook with new entries
5. Flag categories with increasing incident counts
SELECT [System.Id], [System.Title], [System.Description],
       [System.CreatedDate], [System.ClosedDate],
       [System.Tags], [Custom.RootCause]
FROM WorkItems
WHERE [System.WorkItemType] = 'Incident'
  AND [System.State] = 'Closed'
  AND [System.ClosedDate] >= @today - 30
  AND [System.AreaPath] UNDER @AreaPath
ORDER BY [System.ClosedDate] DESC

Apply this: run the runbook agent before the retrospective

Pull the last 30 days of Incident data the day before your sprint retrospective. Patterns that felt anecdotal in the moment become undeniable when the numbers show the same root cause appearing four times. The agent gives the retro something concrete to act on.


The master agent pattern

Individual agents are useful on their own. Orchestration makes them better. A master agent runs all the sub-agents in sequence, handles errors, and produces a summary.

## Master Agent: Populate All Diagrams and Slides

Steps:
1. Calculate start date (2 weeks ago from today)
2. Calculate previous sprint start date (4 weeks ago)
3. Ask user for permission to proceed
4. If approved, run Agent: Update Requestor Patterns
5. Run Agent: Update Request Metrics Summary
6. Run Agent: Key Insights & Improvements
7. Report summary of updates made
8. Suggest running 'make diagrams' to regenerate PNGs

Before executing:
- Display the configuration (project, area path, time period)
- Ask: "I will query Azure DevOps and update diagrams and slides.
  Do you want to proceed? (yes/no)"
- Only proceed if user confirms with "yes"

The confirmation gate is critical. Every agent asks before making changes. The human stays in control.


ADO-specific configuration

The agents work with ADO's specific field model:

ADO concept How agents use it
Area Path Scope queries to team boundaries (Engineering\Platform Consulting)
Iteration Path Map to sprint boundaries for time-based analysis
Work Item Type Filter by Request, Bug, Incident, Task
Custom fields Extract team info from Custom.RequestedTeamName
WIQL The query language — SQL-like, supports DATEDIFF, UNDER, @today
Tags Categorise requests for metric grouping

MCP server setup

The Azure DevOps MCP server connects your AI agent to ADO. Add a .vscode/mcp.json to your project:

{
  "inputs": [
    {
      "id": "ado_org",
      "type": "promptString",
      "description": "Azure DevOps organization name (e.g. 'contoso')"
    }
  ],
  "servers": {
    "ado": {
      "type": "stdio",
      "command": "npx",
      "args": ["-y", "@azure-devops/mcp", "${input:ado_org}"]
    }
  }
}

Authentication happens via the browser — the first time a tool runs, it opens a login prompt for your Microsoft account. No PAT required.

To limit loaded tools, use the -d flag with domains: "args": ["-y", "@azure-devops/mcp", "${input:ado_org}", "-d", "core", "work", "work-items"]. Available domains: core, work, work-items, search, test-plans, repositories, wiki, pipelines, advanced-security.


Anti-patterns to avoid

The hardcoded date tell

The most common breakage in ADO agents is hardcoded date ranges. WHERE ClosedDate >= '2026-03-01' means the query silently returns nothing after the sprint window closes. Always use @today and DATEDIFF — the query should work equally well run today or six months from now.

  • No confirmation gates — Agents that write files without asking lead to surprise changes
  • Hardcoded dates — Use @today and DATEDIFF so queries remain dynamic
  • Querying everything — Scope with Area Path and Work Item Type to keep results relevant
  • Skipping the previous sprint — Trend comparison needs two data points; single-sprint metrics lack context
  • Manual data transfer — If you are copy-pasting from ADO into slides, the agent should be doing it

Getting started

Apply this: one agent at a time

Start with the request metrics agent (Use Case 1). Run it against a real sprint before building the rest. If the WIQL query returns sensible data and the deck updates correctly, add the next agent. Incrementally validated is better than five broken agents at once.

  1. Install the ADO MCP server in your editor
  2. Create an agents.md with one agent (start with request metrics)
  3. Run it against a real sprint
  4. Add agents incrementally as you identify more manual data-gathering tasks

The working examples will be available in the ai-capabilities repo.


Frequently asked questions

Do I need a PAT to connect the ADO MCP server?

No. The @azure-devops/mcp server authenticates via browser OAuth — it opens a Microsoft login prompt the first time a tool runs. No Personal Access Token setup required. The session token is cached locally for subsequent calls.

What if my work items use a custom type instead of 'Request'?

Swap the [System.WorkItemType] = 'Request' filter in the WIQL query for your custom type name (e.g. 'Service Task' or 'Support Item'). Everything else in the query stays the same. You may also need to update the @AreaPath to match where those items live in your project hierarchy.

Can these agents run on a schedule rather than manually?

Yes — wrap the agent invocation in a GitHub Actions workflow with a schedule trigger. The challenge is authentication: scheduled runs cannot do interactive OAuth. You'll need a Service Principal or Managed Identity configured in the ADO MCP server. Check the azure-devops-mcp docs for non-interactive auth options.

How do I handle agents that query multiple Area Paths?

Define @AreaPath as a list and use the UNDER operator: [System.AreaPath] UNDER @AreaPath. You can pass multiple paths as a union query or run the same agent definition with different configuration blocks per team. The master agent pattern handles this naturally — parameterise the config block, run once per area path.

What's the difference between using Tags vs Area Path for categorisation?

Area Path is structural — it reflects your ADO project hierarchy and is hard to change. Tags are additive labels anyone can apply to any work item. For categorising operational requests, Tags are more flexible: teams can tag items as access, pipeline, azure-config without changing the ADO project structure. Use Area Path for team ownership scope, Tags for metric grouping.


Further reading

AI Convention Files: The Complete Taxonomy

Banner image Banner image

AI Convention Files: The Complete Taxonomy

Coding agents have moved beyond simple autocomplete. They can plan work, query APIs, update diagrams, and populate sprint review decks. But they need guidance — and that guidance lives in a growing family of markdown files.

If you have used AGENTS.md, you have seen one piece of the puzzle. There are at least ten more — plus two open protocols (MCP and A2A) that extend the picture beyond files into runtime connectivity and agent-to-agent communication. This post covers every file type and protocol, and explains when to reach for each one. Follow-up posts walk through real-world use cases with working examples for Azure DevOps, GitHub, and Jira.


The ecosystem at a glance

AGENTS.md has the broadest file-level support across VS Code, Cursor, and Claude Code. MCP has the broadest runtime support — it works across VS Code, Cursor, Claude, and ChatGPT. If you can only start with two things: AGENTS.md for instructions, MCP for connectivity.


The file types at a glance

AI convention files taxonomy AI convention files taxonomy

Every AI convention file falls into one of four categories, complemented by two runtime protocols:

Category Files / Protocols When loaded
Always-on instructions AGENTS.md, CLAUDE.md, GEMINI.md, copilot-instructions.md, .cursor/rules/*.md Every session
Path-scoped rules .instructions.md, .claude/rules/*.md When working with matching files
On-demand tasks .prompt.md, SKILL.md When you invoke them
Agent personas .agent.md, .claude/agents/*.md When you switch to that agent
Runtime connectivity MCP servers (tools, resources, prompts) When the agent needs external data
Agent-to-agent A2A protocol (Agent Cards, tasks) When agents collaborate across boundaries

Always-on instructions

These files load at the start of every session. They set the baseline for how agents behave in your project.

AGENTS.md

The open standard. Supported by VS Code, Cursor, GitHub Copilot, and Claude Code (via import). Place it in the repo root. The nearest file in the directory tree takes precedence, so you can override per-folder.

Use it for: workflow steps, quality gates, naming conventions, delivery standards.

# AGENTS.md

## Workflow
1. Plan → scope, success criteria, risks
2. Build → implement with tests
3. Document → update runbooks
4. Release → owner sign-off + monitoring

## Standards
- Naming: <team>-<service>-<env>
- Environments: dev → staging → prod

copilot-instructions.md

GitHub Copilot's repo-wide instruction file. Lives at .github/copilot-instructions.md. Can be auto-generated by the Copilot coding agent.

Use it for: language preferences, framework conventions, test patterns. If you already have AGENTS.md, this can reference it or cover Copilot-specific details.

CLAUDE.md

Anthropic's equivalent. Supports @path imports (including @AGENTS.md to share instructions), .claude/rules/ for path-scoped rules, and auto memory that accumulates across sessions.

.cursor/rules/*.md

Cursor project rules with YAML frontmatter (description, globs, alwaysApply). Four types: Project Rules, User Rules, Team Rules, and native AGENTS.md support.


Path-scoped rules

These load only when the agent works with files matching a glob pattern. They keep context lean and relevant.

.instructions.md (VS Code)

Stored in .github/instructions/. Each file has applyTo frontmatter:

---
applyTo: "infra/**/*.tf"
---
# Terraform conventions
- Use modules from the internal registry
- Tag all resources with team and environment
- No inline IAM policies

.claude/rules/*.md (Claude Code)

Same concept, different location. Uses paths frontmatter:

---
paths:
  - "src/api/**/*.ts"
---
# API rules
- Validate all inputs with Zod
- Use standard error response format

On-demand tasks

These are invoked explicitly, not loaded automatically. They are ideal for repeatable tasks that do not need to be in context all the time.

.prompt.md (slash commands)

Stored in .github/prompts/. Invoked with / in chat. Each prompt can specify which agent and tools to use:

---
description: Generate a migration plan for a database schema change
agent: agent
tools: ['search', 'editFiles']
---
Analyse the current schema and generate a migration plan.
Include rollback steps and estimated downtime.

SKILL.md (portable capabilities)

The open standard from agentskills.io. A skill bundles instructions, scripts, examples, and resources into a reusable capability.

Stored in .github/skills/, .claude/skills/, .agents/skills/, or ~/.copilot/skills/ for personal skills. Skills load on demand — the agent reads the name and description, then loads the full content when it decides the skill is relevant.

---
name: sprint-review-populator
description: Populate a Marp sprint review deck with metrics from GitHub or Jira
argument-hint: Provide the sprint date range
---
# Sprint Review Populator

Query the project tracker for completed work items and update
the deck with real metrics...

Agent personas

Custom agents give the AI a persistent persona with specific tool restrictions, model preferences, and handoffs to other agents.

.agent.md (VS Code)

Stored in .github/agents/. Define specialised roles:

---
description: Read-only security reviewer
tools: ['search', 'web']
handoffs:
  - label: Start Implementation
    agent: implementation
    prompt: Fix the security issues identified above.
---
Review code for OWASP Top 10 vulnerabilities.
Focus on injection, broken access control, and cryptographic failures.

Handoffs create guided workflows — a planning agent hands off to an implementation agent, which hands off to a reviewer.

.claude/agents/*.md (Claude Code)

Claude subagents support tool restrictions, model selection, permission modes, lifecycle hooks, MCP server scoping, and persistent memory that accumulates knowledge across sessions.


Runtime connectivity: MCP servers

Convention files tell agents what to do. MCP (Model Context Protocol) servers give them access to do it. MCP is an open standard — supported by VS Code, Cursor, Claude, ChatGPT, and others — that provides a standardised way for AI agents to connect to external tools, data sources, and workflows.

Think of MCP as USB-C for AI agents. Just as USB-C provides a standardised physical connection, MCP provides a standardised protocol connection. An MCP server exposes three primitives:

Primitive Purpose Example
Tools Executable functions the agent can invoke wiql_query, jql_search, graphql_query
Resources Data sources that provide context File contents, database schemas, API docs
Prompts Reusable interaction templates Few-shot examples, system prompts

MCP uses JSON-RPC 2.0 over stdio (local servers) or Streamable HTTP (remote servers). The key participants:

  • MCP Host — the AI application (VS Code, Cursor, Claude Desktop)
  • MCP Client — a component in the host that maintains a connection to one server
  • MCP Server — a program that provides tools, resources, and prompts

For platform engineering, MCP servers are what connect your AGENTS.md workflows to real systems:

{
  "mcpServers": {
    "github": {
      "command": "npx",
      "args": ["-y", "@modelcontextprotocol/server-github"],
      "env": {
        "GITHUB_PERSONAL_ACCESS_TOKEN": "${env:GITHUB_TOKEN}"
      }
    },
    "jira": {
      "command": "npx",
      "args": ["-y", "@anthropic/mcp-server-jira"],
      "env": {
        "JIRA_URL": "https://your-org.atlassian.net",
        "JIRA_API_TOKEN": "${env:JIRA_API_TOKEN}"
      }
    }
  }
}

Without MCP, agents can only work with local files. With MCP, they can query Jira sprints, GitHub Projects, Azure DevOps boards, Kubernetes clusters, databases, and any system with an MCP server.


Agent-to-agent communication: A2A

MCP connects agents to tools. The Agent2Agent Protocol (A2A) connects agents to each other.

A2A is an open protocol (22.9k GitHub stars, v1.0.0 released, Linux Foundation project) that enables agents built by different vendors, on different frameworks, running on different servers, to collaborate — without sharing internal state, memory, or tools.

Where MCP is vertical (agent ↔ tool), A2A is horizontal (agent ↔ agent):

Protocol Direction Purpose
MCP Agent → Tool Connect agents to external systems (GitHub, Jira, ADO, databases)
A2A Agent → Agent Enable agents to discover, delegate, and collaborate with each other

A2A key concepts:

  • Agent Cards — JSON documents that advertise an agent's capabilities, authentication requirements, and connection details. Other agents discover what you can do by reading your Agent Card.
  • Tasks — The unit of work. A client agent sends a task to a remote agent, which works on it and returns artifacts. Tasks have a lifecycle and support long-running operations.
  • Artifacts — The output of completed tasks. Can be text, files, structured JSON, or rich media.

A practical example: a sprint review orchestrator agent could delegate to specialist agents — one queries Jira via MCP, another generates charts, a third formats the presentation — and A2A handles the communication between them.

A2A complements MCP. Use MCP to connect agents to data sources. Use A2A when you need agents to collaborate across organisational or system boundaries.


Apply this: layer in order

Don't try to set up all seven layers at once. Start with AGENTS.md (it works everywhere). When you hit friction with external system access, add an MCP server. When you need task-specific commands, add .prompt.md files. Add complexity only when you've felt the absence of it.
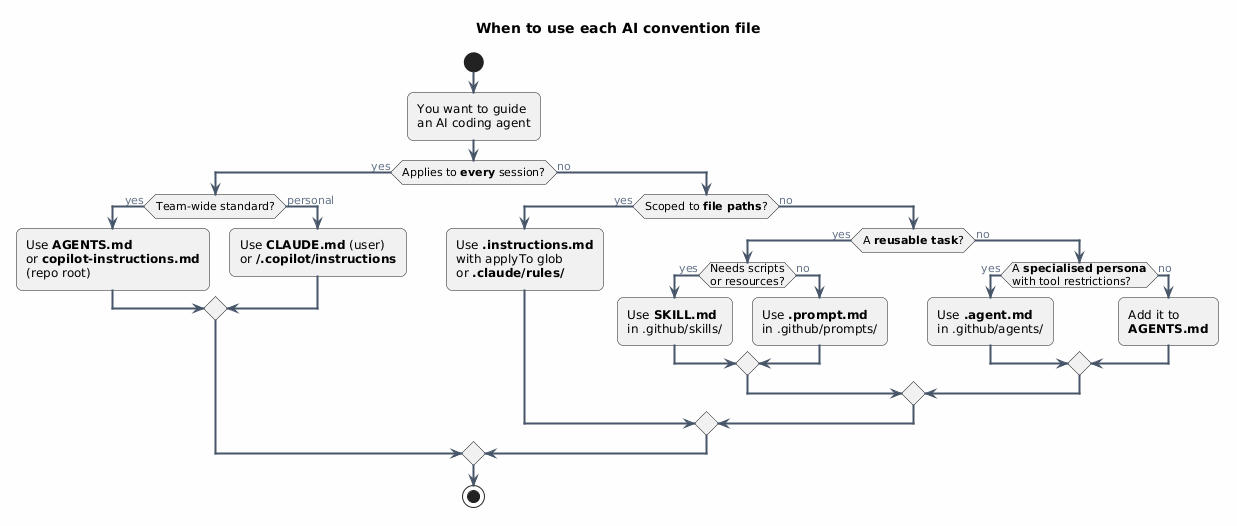
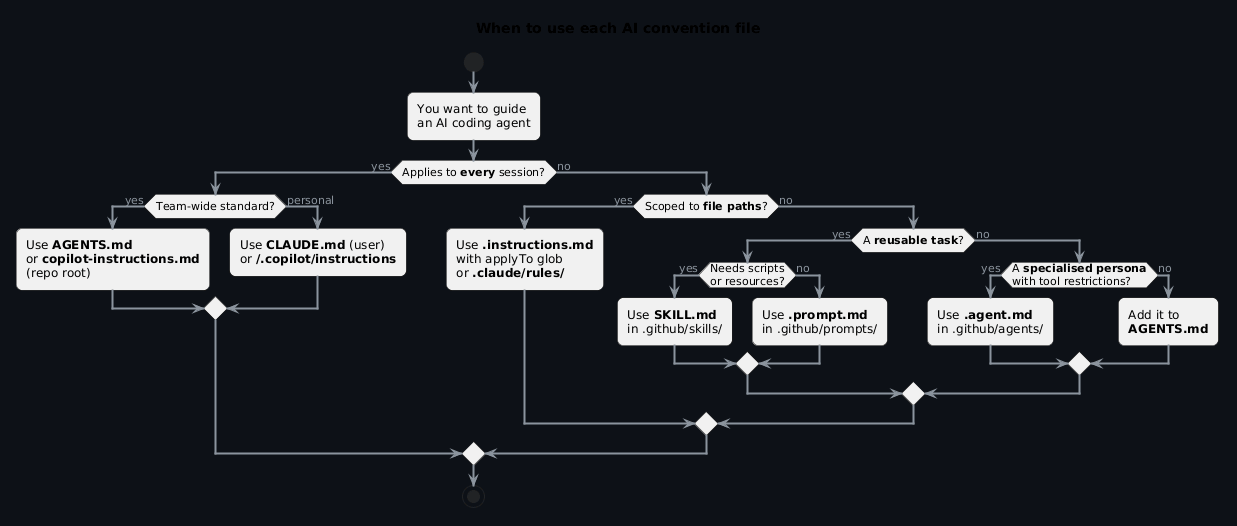
Choosing the right file

Decision flow Decision flow

  1. Applies to every session? → AGENTS.md or copilot-instructions.md
  2. Scoped to specific file paths? → .instructions.md or .claude/rules/
  3. A reusable task with scripts? → SKILL.md
  4. A lightweight slash command? → .prompt.md
  5. A specialised persona with tool restrictions? → .agent.md
  6. Need to connect to an external system? → Add an MCP server
  7. Need agents to collaborate across boundaries? → Use A2A

Where this gets practical

The taxonomy above covers the types. Seeing them work together on concrete problems is where it gets interesting — automated sprint review decks populated from GitHub or Jira, incident runbooks triggered by alerts, infrastructure bootstrap sequences.

Those use cases each have their own post:

Each post includes working agent definitions, real queries, and MCP server configuration. The working code will live in the ai-capabilities repo.


Platform engineering examples

Here is how the file types compose for platform teams:

Path-scoped infrastructure standards

.github/instructions/terraform.instructions.md:

---
applyTo: "infra/**/*.tf"
---
- Use modules from the internal registry
- Tag resources: team, environment, cost-centre
- No inline IAM policies

SRE debugging agent

.github/agents/sre-debugger.agent.md:

---
description: Debug production incidents with read-only access
tools: ['search', 'web', 'terminal']
model: claude-sonnet-4-20250514
---
You are an SRE debugger. Analyse logs, metrics, and traces.
Never modify production resources. Suggest fixes but do not apply them.

Release checklist skill

.github/skills/release-checklist/SKILL.md:

---
name: release-checklist
description: Run the platform release checklist and verify all gates
---
# Release Checklist

1. Verify all tests pass in CI
2. Check dependency vulnerabilities
3. Confirm rollback plan exists
4. Verify monitoring dashboards
5. Get owner sign-off


Product and agile examples

These files are not just for platform engineers. Product teams benefit from the same structure.

Story refinement prompt

.github/prompts/refine-story.prompt.md:

---
description: Refine a user story with acceptance criteria and estimates
agent: ask
---
Given the story title and description, generate:
1. Clear acceptance criteria (Given/When/Then)
2. Technical tasks breakdown
3. Rough estimate (S/M/L)
4. Dependencies and risks

Sprint review prep skill

.github/skills/sprint-review-prep/SKILL.md:

---
name: sprint-review-prep
description: Prepare sprint review talking points from completed work
argument-hint: Provide the sprint name or date range
---
Query completed items, group by epic, and generate
a summary suitable for stakeholder presentation.


The compatibility trap

Not every file works in every tool. .agent.md and .prompt.md are VS Code Copilot-specific. .cursor/rules/ only works in Cursor. CLAUDE.md and .claude/agents/ are Claude Code-specific. Before investing heavily in one format, check the support matrix above against your team's actual tooling.

Cross-tool compatibility

Not every file or protocol works everywhere. Here is the current support matrix:

File / Protocol VS Code Copilot Cursor Claude Code ChatGPT
AGENTS.md Yes Yes Via @AGENTS.md import —
copilot-instructions.md Yes — — —
.instructions.md Yes — — —
.prompt.md Yes — — —
.agent.md Yes — — —
SKILL.md Yes — — —
CLAUDE.md Yes — Yes —
.claude/rules/ — — Yes —
.claude/agents/ Yes — Yes —
.cursor/rules/ — Yes — —
MCP servers Yes Yes Yes Yes
A2A protocol — — — —

AGENTS.md has the broadest file-level support. MCP has the broadest runtime support — it works across VS Code, Cursor, Claude, and ChatGPT. A2A is newer (v1.0.0 released 2025) and client support is still emerging.

Start with AGENTS.md for instructions and MCP for connectivity. Add tool-specific files when you need features that AGENTS.md cannot express (path scoping, tool restrictions, handoffs).


The taxonomy above covers coding-agent convention files — files that live in a project repo and guide agents during development work. Other ecosystems use the same patterns for different purposes.

OpenClaw takes the AGENTS.md / SKILL.md model and applies it to personal AI assistants that operate across messaging channels (WhatsApp, Telegram, Discord, iMessage). OpenClaw adds its own convention files — SOUL.md (identity and tone), MEMORY.md (long-term recall), USER.md (owner context), TOOLS.md (environment-specific notes), and HEARTBEAT.md (proactive background tasks) — that solve problems unique to always-on assistants: session continuity, multi-channel behaviour, and proactive monitoring.

If you are building a personal assistant rather than a coding agent, OpenClaw's file taxonomy is worth studying alongside this one.


How they compose together

In practice, you do not choose one file type and ignore the rest. They layer:

  1. AGENTS.md sets the baseline workflow and standards (works everywhere)
  2. .instructions.md adds path-scoped rules for specific directories
  3. SKILL.md packages reusable capabilities (sprint review, release checklist, incident runbook)
  4. .agent.md defines specialised personas with tool restrictions and handoffs
  5. .prompt.md provides quick slash commands for common tasks
  6. MCP servers provide runtime access to external systems (GitHub, Jira, ADO, databases)
  7. A2A protocol enables cross-boundary agent collaboration

Layers 1–5 are convention files — they tell agents what to do. Layer 6 (MCP) gives agents the ability to act on external systems. Layer 7 (A2A) lets agents delegate to and collaborate with other agents.


Getting started

Pick one:

  • Already using AGENTS.md? Add a SKILL.md for your most repetitive task
  • Want sprint review automation? Read the practice posts for ADO, GitHub, or Jira
  • Need external system access? Add an MCP server for GitHub, Jira, ADO, or your database
  • Need path-scoped rules? Create one .instructions.md for your strictest directory (e.g. infra/)
  • Want agent personas? Create a read-only reviewer .agent.md with limited tools

Start small. Add files as you find real friction, not because the taxonomy says you should.


Frequently asked questions

What's the minimum viable convention file setup for a platform team?

One AGENTS.md at the repo root with your workflow steps, naming conventions, and quality gates. That single file works across VS Code Copilot, Cursor, and Claude Code (via import). Add MCP servers when agents need to reach external systems. Everything else is optional until you have a specific need it solves.

How do SKILL.md files differ from .prompt.md slash commands?

.prompt.md is lightweight — a single prompt template invoked with a slash command, no files or scripts attached. SKILL.md is a bundle: instructions, scripts, example files, and resources packaged together as a reusable capability. Use .prompt.md for quick, text-in/text-out tasks. Use SKILL.md when the capability needs supporting files or multi-step execution.

Can I use AGENTS.md and CLAUDE.md in the same repo?

Yes, and this is the recommended pattern. Put your workflow and standards in AGENTS.md (portable). In CLAUDE.md, add @AGENTS.md to import it, then add only Claude-specific features on top (path imports, .claude/rules/ overrides, memory config). Both files serve the same repo; they answer different tools.

When should I reach for A2A vs just running multiple MCP servers?

MCP connects one agent to one tool. If a single agent needs multiple tools, multiple MCP servers in the same client config is the right answer — no A2A needed. Reach for A2A when you need agents talking to each other: a sprint review orchestrator delegating to a Jira specialist agent and a GitHub specialist agent, each running independently on different infrastructure.

How do I decide what belongs in AGENTS.md vs .instructions.md?

AGENTS.md = rules that apply to the whole repo, every session: workflow, naming conventions, quality gates. .instructions.md = rules scoped to specific file paths that would clutter the root AGENTS.md if added there. Terraform conventions only matter when touching infra/**/*.tf. API rules only matter in src/api/**. Keep the root short; push detail into scoped files.


Further reading

AI Convention Files in Practice: GitHub

Banner image Banner image

AI Convention Files in Practice: GitHub

The taxonomy post covered every AI convention file type. This post puts them to work with GitHub — using GraphQL queries against Issues, Projects V2, Pull Requests, and Actions.

Every example below uses real GraphQL queries and follows patterns suitable for a production agents.md that populates sprint review decks from GitHub project data.


How agents talk to GitHub

An AGENTS.md file defines what the agent should do. A GitHub MCP server provides the runtime connection. The agent reads the workflow, then calls the MCP server to execute GraphQL queries and retrieve project data.

GitHub agents workflow GitHub agents workflow

The GitHub MCP server exposes tools such as graphql_query, list_issues, list_pull_requests, and get_actions_runs. The agent invokes these tools through the MCP protocol — no raw HTTP calls needed.


GraphQL over REST for sprint data

GitHub's REST API requires many round trips to assemble sprint-level data — one call per issue, one call per PR. GraphQL gets nested project items, labels, assignees, and iteration data in a single query. For agents populating a sprint review deck, the difference is 1 call vs 50+. Always use GraphQL when querying Projects V2.

What gets automated (and what does not)

Not everything in a sprint review can come from a query. Platform migrations, new developer tooling, infrastructure redesigns — that work moves through GitHub Projects V2 iterations with milestones and roadmap views, and reporting on it is narrative. What shipped, what slipped, what the team learnt. An agent cannot write that.

Operational work is different. Access provisioning, pipeline fixes, environment configuration, troubleshooting — these arrive as issues, get closed, and pile up. Individually they are routine. In aggregate they tell a story: which labels generate the most volume, how cycle times trend, whether contributor load is balanced. That is numbers, and numbers come from GraphQL.

The agents in this post target operational work. They query GitHub, run the calculations, and drop the results into a Marp sprint review deck. Project slides stay in the same deck as fixed templates — same layout every sprint, content filled in by hand.

In GitHub terms: operations work uses labels like request, support, or ops on a shared repository. Projects track through GitHub Projects V2 with iteration fields, status columns, and tracked issues for epics.


Use case 1: Sprint review deck automation

The same pattern as the ADO version, adapted for GitHub Projects V2. The agent queries completed items from a project iteration, categorises them by label, and updates a Marp deck.

The agent definition

## Agent: Update Sprint Metrics from GitHub

Task: Update deck.md with sprint metrics from GitHub Projects V2

Steps:
1. Query GitHub for items completed in the current iteration
2. Calculate metrics:
   - Count by label category (bug, feature, infra, security)
   - Average cycle time (created → closed)
   - Items completed vs planned (velocity)
   - Unique contributors
3. Show calculated metrics to the user
4. Ask: "Update deck.md with these metrics? (yes/no)"
5. If approved, update the metrics table and key insights
6. Report what was updated

The GraphQL query

query SprintItems($projectId: ID!, $iterationId: String!) {
  node(id: $projectId) {
    ... on ProjectV2 {
      items(first: 100) {
        nodes {
          content {
            ... on Issue {
              title
              number
              state
              createdAt
              closedAt
              labels(first: 10) {
                nodes { name }
              }
              author { login }
              assignees(first: 5) {
                nodes { login }
              }
            }
            ... on PullRequest {
              title
              number
              state
              createdAt
              mergedAt
              author { login }
            }
          }
          fieldValueByName(name: "Iteration") {
            ... on ProjectV2ItemFieldIterationValue {
              title
              startDate
              duration
            }
          }
          fieldValueByName(name: "Status") {
            ... on ProjectV2ItemFieldSingleSelectValue {
              name
            }
          }
        }
      }
    }
  }
}

What the agent produces

Category Count %
Features 12 36%
Bug Fixes 8 24%
Infrastructure 6 18%
Security 4 12%
Documentation 3 9%

Key metrics: 33 items completed, 2.1 day average cycle time, 94% velocity (33/35 planned).


Use case 2: Contributor activity analysis

The GitHub equivalent of ADO's requestor patterns — analysing who is contributing and how work is distributed.

## Agent: Contributor Activity Analysis

Steps:
1. Query GitHub for merged PRs and closed issues in current iteration
2. Group by author/assignee
3. Calculate per-contributor:
   - PRs merged
   - Issues closed
   - Average review turnaround
4. Identify review bottlenecks (PRs waiting > 24 hours)
5. Update the activity summary in the deck
query ContributorActivity($owner: String!, $repo: String!, $since: DateTime!) {
  repository(owner: $owner, name: $repo) {
    pullRequests(
      states: [MERGED]
      orderBy: { field: UPDATED_AT, direction: DESC }
      first: 100
    ) {
      nodes {
        title
        author { login }
        createdAt
        mergedAt
        reviews(first: 10) {
          nodes {
            author { login }
            submittedAt
          }
        }
        additions
        deletions
      }
    }
  }
}

Use case 3: Sprint-over-sprint trend comparison

Comparing the current iteration against the previous one using GitHub Projects V2 iteration fields.

## Agent: Sprint Trend Comparison

Steps:
1. Query current iteration items (status: Done)
2. Query previous iteration items (status: Done)
3. Compare:
   - Velocity change (items completed)
   - Cycle time trend
   - Label distribution shift
   - New contributor count
4. Identify positive trends with percentages
5. Flag areas needing attention
6. Update the Key Insights slide

The agent compares iterations by name:

query IterationComparison($projectId: ID!) {
  node(id: $projectId) {
    ... on ProjectV2 {
      field(name: "Iteration") {
        ... on ProjectV2IterationField {
          configuration {
            iterations {
              id
              title
              startDate
              duration
            }
            completedIterations {
              id
              title
              startDate
              duration
            }
          }
        }
      }
    }
  }
}

Use case 4: Release notes generation

A SKILL.md that generates release notes from merged PRs and closed issues between two tags.

---
name: github-release-notes
description: Generate release notes from merged PRs between two Git tags
argument-hint: Provide the previous and current tag (e.g. v1.2.0 v1.3.0)
---
# GitHub Release Notes Generator

1. List commits between the two tags
2. Find all merged PRs associated with those commits
3. Group PRs by label:
   - 🚀 Features (label: enhancement)
   - 🐛 Bug Fixes (label: bug)
   - 🔧 Infrastructure (label: infra)
   - 🔒 Security (label: security)
   - 📝 Documentation (label: docs)
4. For each PR, extract title, number, and author
5. Generate markdown release notes
6. Check for breaking changes (label: breaking-change)
7. Include contributor acknowledgements
query PRsBetweenTags($owner: String!, $repo: String!, $base: String!, $head: String!) {
  repository(owner: $owner, name: $repo) {
    ref(qualifiedName: $head) {
      compare(headRef: $base) {
        commits(first: 100) {
          nodes {
            message
            associatedPullRequests(first: 1) {
              nodes {
                title
                number
                author { login }
                labels(first: 5) {
                  nodes { name }
                }
              }
            }
          }
        }
      }
    }
  }
}

Use case 5: SLO compliance from issue response times

A prompt that calculates SLO compliance from GitHub issue response and resolution times.

---
description: Generate SLO compliance report from GitHub issue data
agent: agent
tools: ['search', 'editFiles']
---
Query the last 30 days of issues labelled 'support' or 'request'.
Calculate time-to-first-response (issue created → first comment by team member).
Calculate resolution time (issue created → issue closed).
Compare against SLO targets:
- First response: p50 < 2 hours, p90 < 8 hours
- Resolution: p50 < 24 hours, p90 < 72 hours
Generate a markdown table with percentile breakdown and trend.

Use case 6: Actions pipeline health report

An agent that analyses GitHub Actions workflow runs for reliability and performance.

## Agent: Pipeline Health Report

Steps:
1. Query GitHub Actions for workflow runs in the last 14 days
2. Calculate per-workflow:
   - Success rate (%)
   - Average duration
   - Failure patterns (most common failure step)
   - Flaky test detection (intermittent failures)
3. Compare against previous 14-day window
4. Update the pipeline health slide in the deck
5. Flag any workflow with < 90% success rate
query WorkflowRuns($owner: String!, $repo: String!) {
  repository(owner: $owner, name: $repo) {
    object(expression: "main") {
      ... on Commit {
        checkSuites(first: 50) {
          nodes {
            conclusion
            workflowRun {
              workflow { name }
              createdAt
              updatedAt
              runNumber
            }
            checkRuns(first: 20) {
              nodes {
                name
                conclusion
                startedAt
                completedAt
              }
            }
          }
        }
      }
    }
  }
}

The master agent pattern

## Master Agent: Populate Sprint Review from GitHub

Steps:
1. Calculate current iteration dates
2. Ask user for permission to proceed
3. If approved, run Agent: Sprint Metrics
4. Run Agent: Contributor Activity
5. Run Agent: Sprint Trend Comparison
6. Run Agent: Pipeline Health Report
7. Report summary of updates made
8. Suggest running 'make diagrams' to regenerate PNGs

Before executing:
- Display the configuration (org, repo, project, iteration)
- Ask: "I will query GitHub and update diagrams and slides.
  Do you want to proceed? (yes/no)"
- Only proceed if user confirms

GitHub-specific configuration

GitHub concept How agents use it
Projects V2 Track iterations, status fields, and sprint boundaries
Labels Categorise issues and PRs for metric grouping
Milestones Alternative to iterations for release-based tracking
GraphQL API Rich querying with nested fields — more flexible than REST
Actions Pipeline health and deployment frequency metrics
CODEOWNERS Map reviewers to areas for workload analysis

Apply this: set GITHUB_TOOLSETS to limit loaded tools

The GitHub MCP server loads all tools by default. For sprint review agents that only need project data, set GITHUB_TOOLSETS=repos,issues,pull_requests to reduce the tool surface. Fewer tools means less cognitive overhead for the agent and a smaller permission footprint. Load only what the agent actually needs.

MCP server setup

The GitHub MCP server is GitHub's official server. The fastest setup is the remote server, which uses OAuth — no tokens to manage:

{
  "servers": {
    "github": {
      "type": "http",
      "url": "https://api.githubcopilot.com/mcp/"
    }
  }
}

This works in VS Code 1.101+ with Copilot. For editors that do not support remote MCP, use the local Docker-based server with a PAT:

{
  "servers": {
    "github": {
      "command": "docker",
      "args": [
        "run", "-i", "--rm",
        "-e", "GITHUB_PERSONAL_ACCESS_TOKEN",
        "ghcr.io/github/github-mcp-server"
      ],
      "env": {
        "GITHUB_PERSONAL_ACCESS_TOKEN": "${input:github_token}"
      }
    }
  }
}

To limit loaded tools, set GITHUB_TOOLSETS (e.g. repos,issues,pull_requests,actions). See the toolset documentation for the full list.


The hardcoded iteration name tell

Agents that reference a specific sprint by name (sprint = "Sprint 24.06") break every two weeks when the sprint rolls over. Use the IterationField.configuration.iterations query to discover the current iteration dynamically. Your agent should find the active sprint, not be told which one to look at.

Anti-patterns to avoid

  • REST when you need GraphQL — GitHub's REST API requires many round trips; GraphQL gets nested data in one call
  • Ignoring project field types — Projects V2 uses typed fields (iteration, single select, text); query the right type
  • Hardcoded iteration names — Use the iteration field configuration to discover current and previous iterations dynamically
  • Skipping Actions data — Pipeline health is visible early signal; include it in sprint reviews
  • Not filtering by label — Without label-based categorisation, metrics lack the granularity stakeholders need

Getting started

  1. Install the GitHub MCP server in your editor
  2. Create an agents.md with one agent (start with sprint metrics)
  3. Set up a GitHub Project V2 with iteration fields if you have not already
  4. Run the agent against a real iteration
  5. Add agents incrementally

The working examples will be available in the ai-capabilities repo.


Frequently asked questions

Does the GitHub MCP server require a Personal Access Token?

For the remote server (https://api.githubcopilot.com/mcp/) in VS Code 1.101+: no — it uses OAuth via GitHub Copilot. For the Docker-based local server, yes — a PAT with repo, project, and read:org scopes. The remote server is simpler to set up; the local server is needed for editors that don't support remote MCP.

Can agents query private GitHub Projects V2?

Yes, as long as the authenticated token has access. For the remote server, the OAuth flow grants access to your orgs and repos. For the PAT-based local server, ensure the PAT has project scope (classic PAT) or read:project and read:org (fine-grained PAT). Project visibility follows GitHub's existing permission model.

How do you handle Projects V2 with multiple iteration fields?

Query the field(name: "Iteration") with the specific field name you use. If your project has multiple iteration-type fields (e.g. "Sprint" and "Quarter"), query each by name separately. The ProjectV2IterationField.configuration.iterations object gives you the active iteration's startDate and duration so you can calculate boundaries dynamically.

What's the best way to categorise GitHub issues without labels?

Labels are the cleanest signal, but you can also group by assignee (for workload analysis), by milestone (for release tracking), or by the Projects V2 status field (for board column grouping). For teams that haven't adopted a labelling convention yet, milestone-based grouping is the easiest starting point — most teams already use milestones even when labels are inconsistent.

Can the same AGENTS.md work for both GitHub and GitHub Enterprise?

Yes — the GraphQL queries are identical. The only difference is the API endpoint: https://api.github.com/graphql for GitHub.com vs https://your-ghe.example.com/api/graphql for GitHub Enterprise Server. Parameterise the base URL in your MCP server configuration rather than hardcoding it in the agent definitions.


Further reading

AI Convention Files in Practice: Jira

Banner image Banner image

AI Convention Files in Practice: Jira

The taxonomy post covered every AI convention file type. This post puts them to work with Jira — using JQL queries against sprints, boards, components, and fix versions.

Every example below uses real JQL queries and follows patterns suitable for a production agents.md that populates sprint review decks from Jira project data.


How agents talk to Jira

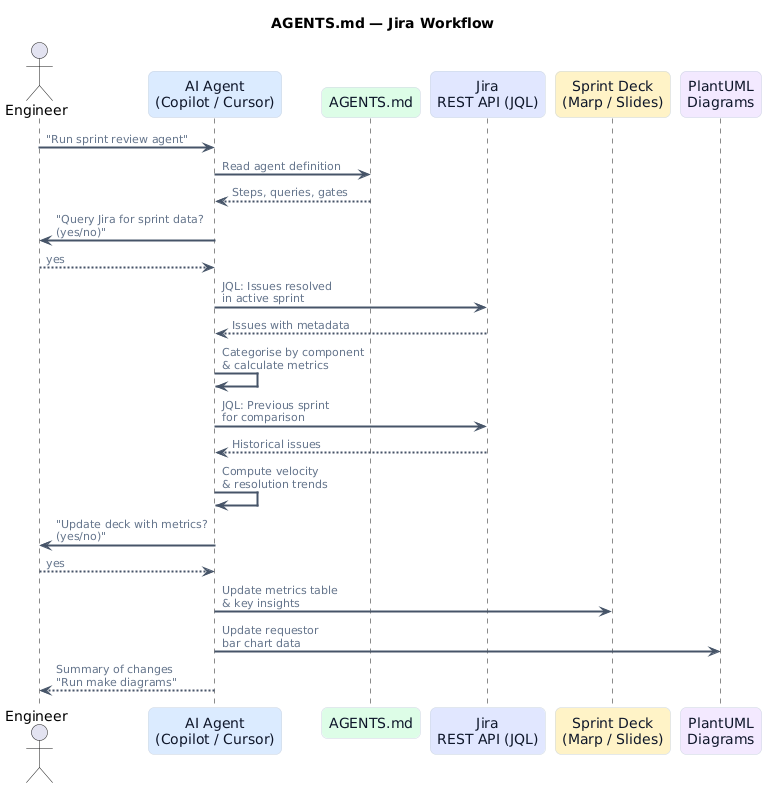
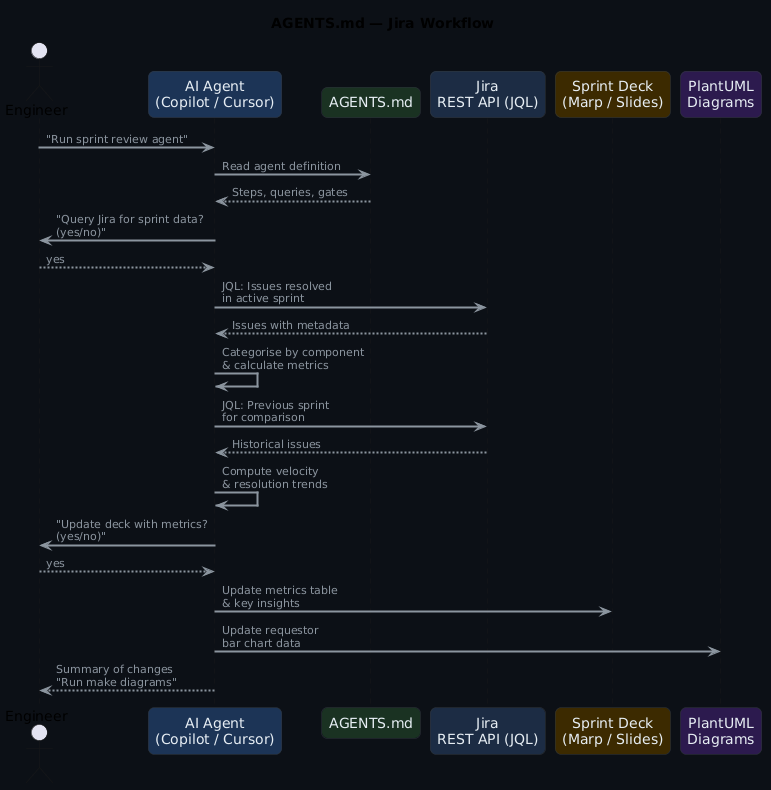
An AGENTS.md file defines what the agent should do. A Jira MCP server provides the runtime connection. The agent reads the workflow, then calls the MCP server to execute JQL queries and retrieve issue data.

Jira agents workflow Jira agents workflow

The Jira MCP server exposes tools such as jql_search, get_issue, get_sprint, and get_board. The agent invokes these tools through the MCP protocol — no raw HTTP calls or API tokens in your agent definitions.


JQL functions beat date ranges

sprint in openSprints() is dynamic — it always targets the active sprint. A hardcoded sprint = "Sprint 24.06" breaks every two weeks. Use Jira's built-in JQL functions (openSprints(), closedSprints(), -14d) so your agent definitions stay valid indefinitely without maintenance.

What gets automated (and what does not)

Not everything in a sprint review can come from a query. Platform migrations, IDP rollouts, infrastructure redesigns — that work moves through Epics and fix versions, and reporting on it is narrative. What shipped, what slipped, what the team learnt. An agent cannot write that.

Operational work is different. Access requests, pipeline failures, environment provisioning, certificate rotations — these arrive as Service Requests, get resolved, and pile up. Individually they are routine. In aggregate they tell a story: which components generate the most load, how resolution times trend, whether the same teams keep coming back. That is numbers, and numbers come from JQL.

The agents in this post target operational work. They query Jira, run the calculations, and drop the results into a Marp sprint review deck. Project slides stay in the same deck as fixed templates — same layout every sprint, content filled in by hand.

In Jira terms: operations work lives in a shared project with types like Service Request or Support, grouped by component. Projects use Epics tracked through sprints and fix versions.


Use case 1: Sprint review deck automation

The agent queries resolved issues from the active sprint, categorises by component, and updates a Marp deck.

The agent definition

## Agent: Update Sprint Metrics from Jira

Task: Update deck.md with sprint metrics from the active Jira sprint

Steps:
1. Query Jira for issues resolved in the active sprint
2. Calculate metrics:
   - Count by component (API, Frontend, Infrastructure, Security)
   - Average resolution time (created → resolved)
   - Story points completed vs committed (velocity)
   - Unique assignees
3. Show calculated metrics to the user
4. Ask: "Update deck.md with these metrics? (yes/no)"
5. If approved, update the metrics table and key insights
6. Report what was updated

The JQL query

project = "PLAT"
  AND sprint in openSprints()
  AND status = Done
  AND resolved >= -14d
ORDER BY resolved DESC

For more granular filtering:

project = "PLAT"
  AND sprint = "Sprint 24.06"
  AND status changed to Done
  AND component in (API, Frontend, Infrastructure, Security)
ORDER BY component ASC, resolved DESC

What the agent produces

Component Count Story Points %
API 10 21 30%
Frontend 8 18 24%
Infrastructure 7 15 21%
Security 4 8 12%
Documentation 3 5 9%
DevOps 1 2 3%

Key metrics: 33 issues resolved, 69 story points completed (92% of committed 75), 2.3 day average resolution.


Use case 2: Team workload analysis

The Jira equivalent of requestor patterns — analysing assignee distribution and identifying workload imbalances.

## Agent: Team Workload Analysis

Steps:
1. Query Jira for issues resolved in the active sprint
2. Group by assignee
3. Calculate per-assignee:
   - Issues resolved
   - Story points completed
   - Average resolution time
4. Identify workload imbalances (> 2x average)
5. Check for unassigned resolved issues
6. Update the workload summary in the deck
project = "PLAT"
  AND sprint in openSprints()
  AND status = Done
  AND assignee is not EMPTY
ORDER BY assignee ASC

Use case 3: Sprint-over-sprint velocity comparison

Comparing the current sprint against the previous one using Jira's sprint functions.

## Agent: Velocity Trend Comparison

Steps:
1. Query current sprint issues (status: Done)
2. Query previous sprint issues (status: Done)
3. Compare:
   - Story points completed (velocity)
   - Issue count
   - Average cycle time
   - Component distribution shift
   - Carry-over items (not completed in previous sprint)
4. Identify positive trends with percentages
5. Flag areas needing attention
6. Update the Velocity Trends slide
-- Current sprint
project = "PLAT" AND sprint in openSprints() AND status = Done

-- Previous sprint
project = "PLAT" AND sprint in closedSprints()
  AND sprint not in openSprints()
  AND status = Done
ORDER BY resolved DESC

For named sprints:

project = "PLAT" AND sprint = "Sprint 24.05" AND status = Done

Use case 4: Release notes from fix versions

A SKILL.md that generates release notes from a Jira fix version.

---
name: jira-release-notes
description: Generate release notes from a Jira fix version
argument-hint: Provide the fix version name (e.g. v2.4.0)
---
# Jira Release Notes Generator

1. Query issues with the specified fixVersion
2. Verify all issues are in Done status
3. Flag any non-Done issues as blockers
4. Group issues by type:
   - 🚀 Features (type: Story)
   - 🐛 Bug Fixes (type: Bug)
   - 🔧 Tasks (type: Task)
   - 📖 Sub-tasks (type: Sub-task)
5. For each issue, extract:
   - Key, summary, component, assignee
   - Labels for additional context
6. Generate markdown release notes
7. Check for issues labelled 'breaking-change'
8. Include contributor acknowledgements from assignee list
project = "PLAT"
  AND fixVersion = "v2.4.0"
ORDER BY issuetype ASC, component ASC

Use case 5: SLO compliance from resolution times

A prompt that calculates SLO compliance from Jira issue resolution data.

---
description: Generate SLO compliance report from Jira issue data
agent: agent
tools: ['search', 'editFiles']
---
Query the last 30 days of issues with type 'Service Request' or 'Support'.
Calculate resolution time percentiles (p50, p90, p99).
Use the 'resolutiondate' and 'created' fields for time calculations.
Compare against SLO targets:
- p50 < 4 hours (Priority: Highest)
- p50 < 24 hours (Priority: High)
- p90 < 72 hours (Priority: Medium/Low)
Generate a markdown table grouped by priority with trend arrows.
project = "PLAT"
  AND issuetype in ("Service Request", Support)
  AND resolved >= -30d
ORDER BY priority ASC, resolved DESC

Use case 6: Epic progress dashboard

An agent that summarises epic progress for stakeholder reviews.

## Agent: Epic Progress Dashboard

Steps:
1. Query Jira for active epics in the project
2. For each epic:
   - Count total child issues
   - Count completed child issues
   - Sum story points (completed vs total)
   - Calculate completion percentage
   - Find the earliest and latest due dates
3. Rank epics by completion percentage
4. Flag at-risk epics (< 50% complete with < 25% time remaining)
5. Update the Epic Progress slide in the deck
-- Active epics
project = "PLAT"
  AND issuetype = Epic
  AND status != Done
ORDER BY priority ASC

-- Child issues for a specific epic
"Epic Link" = PLAT-123 AND status = Done

The master agent pattern

## Master Agent: Populate Sprint Review from Jira

Steps:
1. Identify the active sprint name
2. Ask user for permission to proceed
3. If approved, run Agent: Sprint Metrics
4. Run Agent: Team Workload Analysis
5. Run Agent: Velocity Trend Comparison
6. Run Agent: Epic Progress Dashboard
7. Report summary of updates made
8. Suggest running 'make diagrams' to regenerate PNGs

Before executing:
- Display the configuration (project, board, sprint)
- Ask: "I will query Jira and update diagrams and slides.
  Do you want to proceed? (yes/no)"
- Only proceed if user confirms

Jira-specific configuration

Jira concept How agents use it
Projects Scope queries by project key (project = "PLAT")
Sprints Use openSprints(), closedSprints(), or named sprints
Components Categorise issues for metric grouping (API, Frontend, Infra)
Fix Versions Map to release milestones for release notes generation
Story Points Calculate velocity and sprint commitment accuracy
JQL The query language — supports functions like openSprints(), -14d, was, changed
Boards Scrum or Kanban views that scope sprint data

Apply this: set Jira defaults in AGENTS.md to save tokens

Add a configuration block to your AGENTS.md that sets the project key, board ID, and maxResults defaults once. Agents inherit these without repeating them in every JQL query definition. Fewer tokens per call, less chance of an agent querying the wrong project when operating across multiple Jira projects.

MCP server setup

The Atlassian MCP server is a remote server hosted by Atlassian that connects to Jira, Confluence, and Compass. For VS Code and other clients that support remote MCP:

{
  "servers": {
    "atlassian": {
      "type": "http",
      "url": "https://mcp.atlassian.com/v1/mcp"
    }
  }
}

Authentication uses OAuth 2.1 — a browser window opens to authorise your Atlassian account. All actions respect your existing Jira permissions.

For desktop clients that do not support remote MCP natively (e.g. Claude Desktop, Cursor), use the mcp-remote proxy:

{
  "mcpServers": {
    "atlassian": {
      "command": "npx",
      "args": ["-y", "mcp-remote", "https://mcp.atlassian.com/v1/sse"]
    }
  }
}

To reduce discovery calls and save tokens, set defaults in your AGENTS.md:

When connected to atlassian-rovo-mcp:
- Use Jira project key = PLAT
- Use cloudId = "https://your-site.atlassian.net"
- Use maxResults: 10 for all JQL search operations

Issue count without story points misleads stakeholders

Reporting "33 issues resolved" without story points hides effort. A sprint with 33 one-point bug fixes looks identical to one with 33 complex feature stories. Always report both: issue count for volume, story points for effort. If your team doesn't use story points, at least report by issue type distribution.

Anti-patterns to avoid

  • Querying by date instead of sprint — Jira sprints have boundaries; use sprint in openSprints() instead of date ranges to capture carry-overs correctly
  • Ignoring story points — Issue count alone does not reflect effort; include story points in velocity calculations
  • Not using components — Without component-based grouping, sprint metrics lack actionable granularity
  • Skipping epic context — Individual issue metrics miss the bigger picture; include epic progress for stakeholders
  • Hardcoded sprint names — Use openSprints() and closedSprints() functions for dynamic sprint identification

Getting started

  1. Install the Jira MCP server in your editor
  2. Create an agents.md with one agent (start with sprint metrics)
  3. Ensure your Jira project has components and story points configured
  4. Run the agent against a real sprint
  5. Add agents incrementally

The working examples will be available in the ai-capabilities repo.


Frequently asked questions

Does the Atlassian MCP server require admin access to Jira?

No — it uses OAuth 2.1 and respects your existing Jira permissions. The agent can only query and act on projects, boards, and issues you have access to as the authenticated user. No elevated permissions required. Admin access would only be needed if an agent were creating boards or modifying project configuration.

How do agents handle Jira custom fields?

Custom fields are accessible via their field ID (e.g. cf[10016] for story points, depending on your Jira instance). The Atlassian MCP server exposes field metadata so agents can discover field IDs dynamically. For common custom fields you use repeatedly, add the field IDs to your AGENTS.md configuration block so agents don't have to look them up every run.

Can I run the same agent against multiple Jira projects?

Yes — parameterise @ProjectKey in the JQL queries and define it in the AGENTS.md configuration block. Run the master agent once per project by changing the config block. For teams with a shared operations project and multiple product projects, run ops metrics from one project and velocity from another in the same deck session.

What's the difference between using Jira sprints vs fix versions for release tracking?

Sprints are time-boxed iterations — good for velocity, cycle time, and operational metrics. Fix versions are milestone markers — good for release scope, scope creep tracking, and what shipped in a version. Use sprints for the sprint review deck. Use fix versions for release notes and stakeholder communication. They answer different questions.

How do you avoid the 'open sprints' query returning items from multiple active sprints?

In Jira, sprint in openSprints() returns all active sprints, which can include sprints on different boards. Scope it with the project key and board ID: query the board's active sprint directly via the Jira Agile API (/rest/agile/1.0/board/{boardId}/sprint?state=active) or add AND sprint = "Sprint 24.XX" with the dynamically discovered sprint name. The MCP server's get_sprint tool handles this cleanly.


Further reading

Sprint Reviews with Marp: Presentations as Code

Banner image Banner image

Sprint Reviews with Marp: Presentations as Code

Sprint review decks have a shelf life of about two weeks. You build one, present it, then build the next one — mostly from scratch. The metrics change, the charts update, the talking points shift. But the structure stays the same.

That repetition is the problem. Manually pulling numbers from Azure DevOps, rebuilding bar charts, updating summary tables — it takes time and introduces mistakes. If the deck is a PowerPoint file, diffs are meaningless and merge conflicts are impossible to resolve.

Here's the insight that makes this tractable: not everything in a sprint review is the same kind of work.

Platform development — building new self-service capabilities, golden paths, reference architectures — is project-shaped. It has objectives, milestones, design decisions, and demos. A sprint review slide for a platform initiative needs narrative: what shipped, what slipped, what the team learnt. An agent can't write that. But the template can stay fixed — same layout, same sections, filled in by the team each sprint.

BAU and operations — access provisioning, pipeline troubleshooting, infrastructure requests — is ticket-shaped. The metrics matter more than the individual items. Request counts by category, resolution time trends, SLA compliance, top requesting teams — the numbers change every sprint, the format does not. Agents query the tracker, run the calculations, and write the results straight into the deck.

Most platform teams do both. The sprint review deck reflects that split. Operations slides are agent-populated. Platform development slides use fixed templates. The whole structure lives in version control.

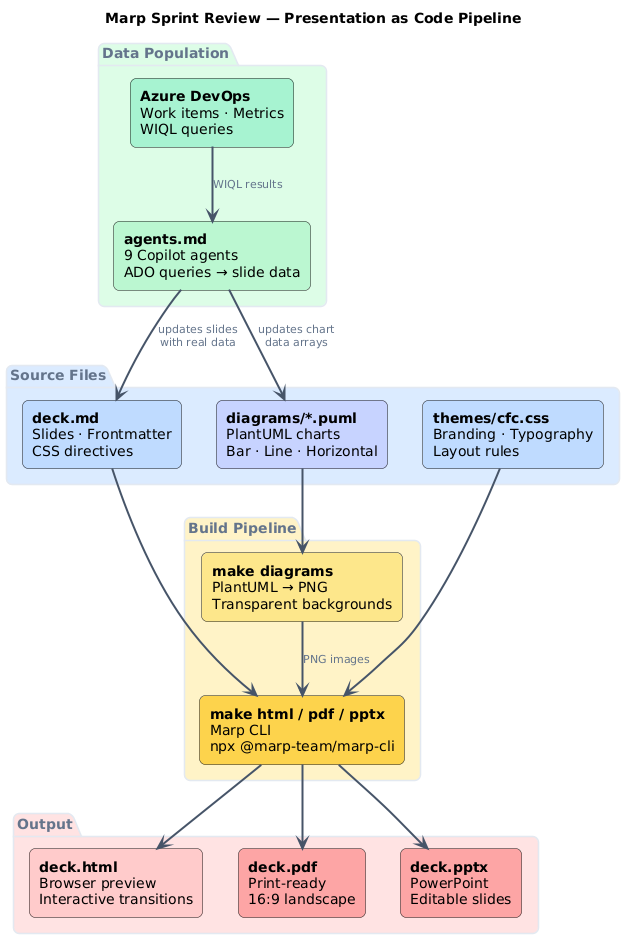
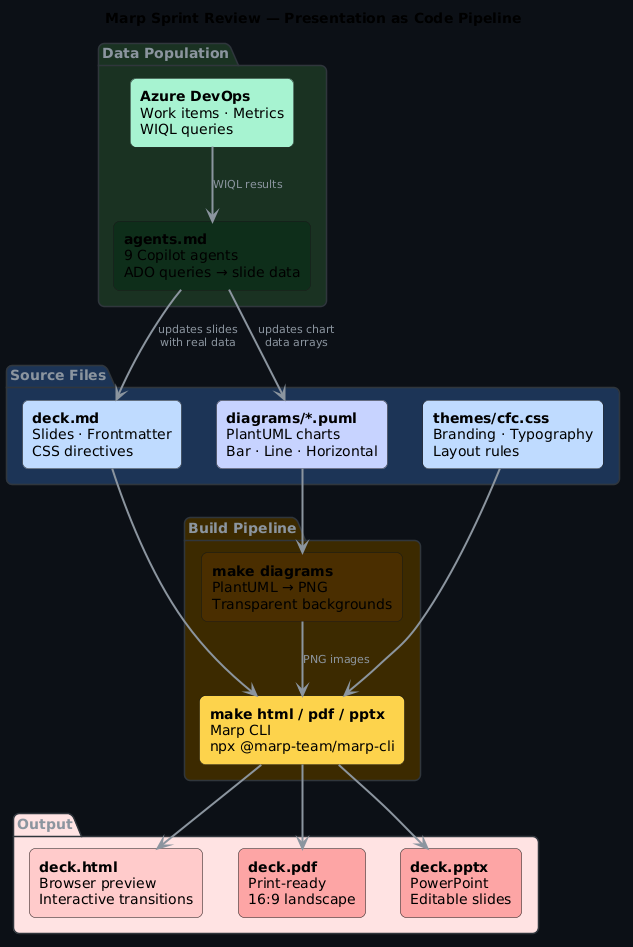
Marp solves the structural half: slides written in Markdown, version-controlled in Git, rendered to HTML, PDF, or PowerPoint. AGENTS.md solves the data half: Copilot agents that query ADO and write the numbers directly into the deck.

This post walks through both — the deck format and the automation layer on top of it.


Diffs are the hidden superpower of Markdown slides

When you update sprint metrics in a Marp deck, git diff shows exactly what changed — "Total requests: 42 → 47", "SLA compliance: 85% → 91%". In PowerPoint, that diff is invisible. A version-controlled deck gives you an audit trail of every sprint's numbers without any extra tooling. That alone is worth the migration from slide software.


What Marp does

Marp is a Markdown-based presentation framework. You write slides in a .md file, add a YAML frontmatter block for configuration, and use --- to separate slides. The Marp CLI converts the Markdown to HTML, PDF, or PPTX.

A minimal slide deck:

---
marp: true
theme: default
paginate: true
---

# Slide One

Content goes here.

---

# Slide Two

More content.

That produces a two-slide deck with pagination. No drag-and-drop, no binary format, no GUI.

Why this matters for sprint reviews

  • Diffs work. When you update metrics, git diff shows exactly what changed — "Total requests: 42 → 47". PowerPoint diffs are opaque.
  • Templates carry forward. The slide structure persists across sprints. You update the data, not the layout.
  • Build pipeline. make html produces a browser preview. make pdf produces a print-ready output. make pptx produces a PowerPoint for stakeholders who need one. One source, three formats.
  • No context switching. The deck lives in VS Code alongside the agents.md that populates it.

Deck structure

A production sprint review deck uses frontmatter to configure the theme, transitions, and language:

---
title: "Platform Engineering Sprint Review"
marp: true
theme: copernicus
transition: fade
size: "16:9"
lang: en-GB
paginate: true
header: "Platform Engineering"
---

The theme: copernicus directive loads a custom CSS theme from a themes/ directory. This keeps branding consistent without embedding styles in every slide. The Marp community themes page is a good starting point; drop any .css file into a local themes/ folder and reference it by filename.

Slide content

Slides use standard Markdown — headers, bullet lists, tables, images. Marp adds a few directives for layout control:

<!-- _class: title -->

# Sprint Review

---

## DD Month YYYY

![bg right:40%](images/external/banner.png)

The _class: title directive applies a CSS class to that slide only. bg right:40% places a background image on the right side of the slide.

Tables render natively:

| Category              | Count | % of Total |
|-----------------------|-------|------------|
| Access & Permissions  | 12    | 28%        |
| Pipeline & CI/CD      | 9     | 21%        |
| Azure Resources       | 7     | 16%        |

No chart plugins, no embedded objects — plain text that any editor can open.


PlantUML charts in slides

Static tables work for summaries. For visual metrics — category distributions, resolution time trends, team volumes — PlantUML charts generate PNGs that slot directly into slides.

A bar chart for request distribution:

@startchart
title Request Category Distribution

bar "Category" [
  "Access & Perms" 12,
  "Pipeline" 9,
  "Azure Config" 7,
  "Infra Setup" 6,
  "APIM" 4,
  "DR" 2,
  "Other" 2
] #3498db labels

@endchart

Running PlantUML converts this to a PNG with a transparent background:

java -jar ~/tools/plantuml-snapshot.jar diagrams/request-distribution.puml -o .

The slide references the generated image:

---

## Request Distribution

![Request categories](diagrams/request-distribution.png)

The chart data is plain text in a .puml file. When the agent updates the numbers, git diff shows "Access & Perms" 12 → "Access & Perms" 15. Try that with an embedded Excel chart.

Chart types used

The sprint review deck uses six PlantUML charts:

Chart Type Shows
Request distribution Horizontal bar Category breakdown
Resolution time trends Line Daily averages over 14 days
Request complexity Bar Simple / Medium / Complex split
Request lifecycle SLA Horizontal bar Stage timings in hours
Requestor patterns Horizontal bar Top 5 requesting teams
Top teams volume Horizontal bar Team request volumes

All six are generated with make diagrams, which runs PlantUML across every .puml file in the diagrams/ directory.


Apply this: separate narrative slides from data slides in your deck structure

The two-type model works best when it's structurally visible in the deck. Name your platform development slides with a fixed marker (<!-- PROJECT -->) and your operations slides with a data marker (<!-- OPS - auto-populated -->). This makes it obvious to anyone opening the file which slides the agent owns and which the team fills in. It also prevents the agent from accidentally overwriting a hand-written narrative section.


How AGENTS.md populates the deck

The taxonomy post covered what AGENTS.md files do. The ADO practice post showed WIQL query patterns. This deck uses both.

An agents.md file sits alongside deck.md in the repo. It defines nine agents, each responsible for a specific section of the deck. Three tracker-specific variants are available in the repo:

Tracker File Query language
Azure DevOps agents.md WIQL
GitHub Projects agents-github.md GraphQL
Jira agents-jira.md JQL

The structure is identical across all three — same nine agents, same master agent, same deck update targets. Only the query language and field names differ.

The workflow:

  1. Open the relevant agents.md for your tracker in VS Code
  2. Ask Copilot: "Run Master Agent: Populate All Diagrams and Slides"
  3. The master agent runs each sub-agent in sequence
  4. Each sub-agent queries your tracker via MCP, then writes the results into deck.md or a .puml file
  5. Run make diagrams to regenerate PNGs
  6. Run make html to preview

Agent examples

Agent 5 — Requestor Patterns queries ADO for all Requests in the current sprint, groups by requesting team, counts totals, and updates diagrams/requestor-patterns.puml with the top five teams:

Steps:
1. Query ADO for all Requests from last 2 weeks
2. Extract requesting team from Custom.RequestedTeamName
3. Group by team, count requests
4. Update bar data array in requestor-patterns.puml

The WIQL query:

SELECT [System.Id], [System.Title], [Custom.RequestedTeamName]
FROM WorkItems
WHERE [System.WorkItemType] = 'Request'
  AND [System.AreaPath] UNDER @AreaPath
  AND [System.CreatedDate] >= @StartDate

The @AreaPath parameter is defined once in the agents.md configuration block, so the same agents work across different teams without editing every query.

Agent 6 — Request Metrics Summary does arithmetic: counts by category, calculates SLA compliance percentages, finds the peak request day, then writes a Markdown table into the "Operations Overview" slide of deck.md.

Agent 8 — Key Insights compares the current sprint against the previous one. It calculates resolution time changes, SLA shifts, and volume trends, then updates the "Key Insights & Improvements" slide with data-backed bullet points.

The master agent

A master agent orchestrates the others:

Steps:
1. Calculate start date (2 weeks ago)
2. Ask user for permission to query ADO
3. Run Agent 5: Update Requestor Patterns
4. Run Agent 6: Update Request Metrics Summary
5. Run Agent 8: Update Key Insights
6. Report summary of updates
7. Suggest running 'make diagrams'

Each agent asks for confirmation before writing. The master agent handles sequencing and error recovery — if one agent fails (say, ADO returns no data for a category), it reports the issue and moves to the next.

Marp sprint review pipeline Marp sprint review pipeline


The stale placeholder tell

The most common failure mode in agent-populated decks is a slide that still shows last sprint's numbers because one agent silently returned no data and left the previous values in place. Add a freshness check: after the master agent runs, scan deck.md for any placeholder patterns (e.g. <!-- UPDATE --> markers or dates older than 14 days). If found, flag it before presenting — stale numbers in a sprint review erode trust fast.


The build pipeline

The Makefile (macOS/Linux) and make.bat (Windows) handle the full pipeline:

# Generate all outputs
make all        # diagrams + HTML + PDF + PPTX

# Individual targets
make diagrams   # PlantUML → PNG
make html       # Marp → HTML (fast preview)
make pdf        # Marp → PDF
make pptx       # Marp → PowerPoint

make html produces a self-contained HTML file you can open in a browser. Slide transitions work. Navigation works. Presenter notes show up in presenter mode (P key). It runs in under two seconds.

make pptx produces a real PowerPoint file for stakeholders who need to open it in Office. The formatting isn't pixel-perfect — Marp-to-PPTX conversion has limitations — but it's close enough for most uses.


Sprint workflow

A typical two-week cycle:

  1. Sprint start — Run the master agent to populate the deck with data from the previous sprint (or stub in the current sprint dates).
  2. During the sprint — No deck work needed. Focus on delivery.
  3. Sprint end — Run the master agent again. It pulls fresh ADO data — completed requests, resolution times, SLA figures — and writes everything into deck.md and the .puml files.
  4. Review prep — make all generates HTML for presenting and PDF/PPTX for distribution. Add any manual commentary (demo notes, shout-outs) directly in deck.md.
  5. Present — Open the HTML in a browser. Use F for full-screen, P for presenter mode.
  6. Archive — Commit and push. The deck is versioned. Next sprint, reset the data and start again.

Total manual effort: running the master agent and adding commentary. The charts, tables, and metrics fill themselves.


Getting started

To set up a similar deck:

  1. Install Marp CLI: npm install -g @marp-team/marp-cli
  2. Install PlantUML: Download the snapshot JAR to ~/tools/plantuml-snapshot.jar
  3. Create deck.md: Start with the frontmatter block from above, add --- separators for slides
  4. Pick your agents.md: Use agents.md for ADO, agents-github.md for GitHub Projects, or agents-jira.md for Jira. Set the configuration block at the top (area path, project key, or repo owner) and all nine agents pick it up.
  5. Add a Makefile: Wire up marp and plantuml commands
  6. Run the workflow: Agent → data → make all → present

The AI Convention Files taxonomy covers the full set of file types available. The ADO practice post has WIQL query patterns you can adapt.


Companion resources

A working starter — deck.md template, PlantUML chart files, Makefile, and generate-deck.sh — is in the ai-capabilities repo. The nine-agent workflow is available for all three major trackers:

Further reading:


Frequently asked questions

Does Marp work on Windows, or is it Mac/Linux only?

Marp CLI is cross-platform — it runs on Windows, macOS, and Linux via Node.js. The Makefile in the companion repo uses standard Unix commands; for Windows use the included make.bat instead. PlantUML requires Java, which is also cross-platform. The VS Code Marp extension provides a live preview that works identically across all platforms.

Can I use a custom theme that matches our company branding?

Yes — drop any CSS file into a themes/ directory and reference it in the deck frontmatter with theme: your-theme-name. The Marp CSS spec supports custom fonts, colour palettes, and slide classes. The copernicus theme used in these examples is a custom theme defined in the companion repo; you can use it as a starting point and swap in your brand colours.

What happens if the agent updates deck.md with wrong numbers?

Every agent asks for confirmation before writing: "Update deck.md with these metrics? (yes/no)". Review the calculated numbers before approving. If wrong numbers do get written, git diff shows exactly what changed and git revert or git checkout restores the previous version in one command. This is the core value of keeping the deck in Git rather than a shared drive file.

Do all three tracker versions (ADO, GitHub, Jira) use exactly the same deck structure?

Yes — the nine-agent workflow and deck structure are identical across all three. Only the query language and field names differ (WIQL vs GraphQL vs JQL). You can run your review prep against whichever tracker your team uses without changing the slide template. The companion repo has all three agents.md variants alongside a single deck.md template.

How do you handle the PlantUML chart generation on CI — is Java required in the pipeline?

Yes — make diagrams calls the PlantUML JAR, which requires Java. For CI, either include a Java installation step or pre-generate the PNGs locally and commit them alongside the .puml source files. Most teams commit generated PNGs to Git (the source .puml is the truth; the PNG is the render) and only regenerate in CI when a .puml file changes.

OpenClaw Convention Files: AI Assistants Beyond Code

Banner image Banner image

OpenClaw Convention Files: AI Assistants Beyond Code

The taxonomy post covered convention files for coding agents — AGENTS.md, SKILL.md, .prompt.md, and their relatives. Those files live in a project repo and guide agents during development work.

OpenClaw uses the same approach for a different problem: personal AI assistants that operate across messaging channels. An OpenClaw agent can reply to WhatsApp messages, monitor Discord servers, check email, control smart home devices, and run background tasks — all from a single gateway process on your own hardware.

The convention files that power this are different from the coding-agent ones, because the problems are different. A coding agent needs workflow steps and quality gates. A personal assistant needs identity, memory across sessions, and rules about when to speak in group chats.


The file types

OpenClaw convention files taxonomy OpenClaw convention files taxonomy

File Purpose When loaded
AGENTS.md Behavioural baseline — safety, workflow, skills, session rules Every session start
SOUL.md Identity, tone, and boundaries — who the agent is Every session start
USER.md Owner context — who the agent is helping Every session start
MEMORY.md Long-term recall — curated facts, preferences, decisions Main session only (not group chats)
memory/YYYY-MM-DD.md Daily logs — raw notes from each session Today + yesterday on startup
TOOLS.md Environment specifics — device names, SSH hosts, voice preferences When a skill needs it
SKILL.md Per-skill instructions — one per tool/capability When the skill is invoked
HEARTBEAT.md Background task checklist — what to check during idle polls On heartbeat poll
BOOTSTRAP.md First-run identity setup — read once, then deleted First session only

Three of these (AGENTS.md, SOUL.md, USER.md) load on every session start, before the agent responds to anything. The rest load on demand.


Three files load on every session start — get those right first

AGENTS.md, SOUL.md, and USER.md load before the agent responds to anything. These three files define the agent's behaviour baseline, identity, and understanding of who it's helping. Everything else — MEMORY.md, TOOLS.md, HEARTBEAT.md — loads on demand. Invest your setup time in the always-on three before touching the rest.


AGENTS.md — the behavioural baseline

OpenClaw's AGENTS.md shares the name with the coding-agent standard but serves a broader role. It covers:

  • Safety defaults — no directory dumps, no destructive commands without asking, no partial replies to messaging surfaces
  • Session startup — read SOUL.md, USER.md, and recent memory files before responding
  • Shared spaces — rules for group chat behaviour, including when to stay quiet
  • Memory system — how daily logs and long-term memory work together
  • Tools & skills — where skill instructions live and how to use TOOLS.md

A stripped-down version:

# AGENTS.md


---

## Safety defaults
Don't dump directories or secrets into chat.
Don't run destructive commands unless explicitly asked.


---

## Session start (required)
Read SOUL.md, USER.md, and today+yesterday in memory/.
Do it before responding.


---

## Memory
Daily notes: memory/YYYY-MM-DD.md
Long-term: MEMORY.md — curated memories, loaded in main session only.
Capture decisions, preferences, constraints, open loops.


---

## Tools & skills
Tools live in skills; follow each skill's SKILL.md when you need it.
Keep environment-specific notes in TOOLS.md.

The key difference from a coding-agent AGENTS.md: OpenClaw's version must handle multi-channel behaviour. A coding agent works in one editor session. An OpenClaw agent might be in a private WhatsApp chat, a Discord server, and monitoring email — simultaneously.


SOUL.md — identity and personality

This is the file that does not exist in the coding-agent world. SOUL.md defines who the agent is — not what it does, but how it thinks and communicates.

From OpenClaw's template:

# SOUL.md


---

## Core Truths
Be genuinely helpful, not performatively helpful.
Skip the "Great question!" and "I'd be happy to help!" — just help.

Have opinions. You're allowed to disagree, prefer things,
find stuff amusing or boring.

Be resourceful before asking. Try to figure it out.
Read the file. Check the context. Search for it.
Then ask if you're stuck.


---

## Boundaries
Private things stay private. Period.
When in doubt, ask before acting externally.
You're not the user's voice — be careful in group chats.


---

## Vibe
Be the assistant you'd actually want to talk to.
Concise when needed, thorough when it matters.
Not a corporate drone. Not a sycophant. Just… good.

A couple of things worth noting:

The "have opinions" line. Most coding-agent instructions deliberately suppress personality — you want a consistent, neutral tool. OpenClaw takes the opposite approach. A personal assistant that sounds like a press release is worse than useless when you are messaging it at 11pm asking about dinner plans.

The file belongs to the agent. SOUL.md can be updated by the agent itself, not just the owner. If the agent's personality evolves over time, it records that. The instruction is: "If you change this file, tell the user."


MEMORY.md and daily logs — session continuity

Every AI agent has the same fundamental problem: it wakes up fresh each session with no memory of what happened before. Coding agents solve this with project files and git history — the code is the memory. Personal assistants need something else.

OpenClaw splits memory into two tiers:

Daily logs (memory/YYYY-MM-DD.md) — raw notes from each session. Decisions made, things discussed, tasks completed. The agent creates these automatically and reads today plus yesterday on startup.

Long-term memory (MEMORY.md) — curated facts that matter across days and weeks. Preferences, recurring patterns, important context. The agent periodically reviews daily logs and distills them into MEMORY.md, like a human reviewing their journal.

The security boundary matters: MEMORY.md only loads in the main session (direct chat with the owner). In group chats or shared channels, it stays unread. Personal context should not leak to strangers.

# MEMORY.md — Long-term Memory

ONLY load in main session (direct chats with your human).
DO NOT load in shared contexts (Discord, group chats).
Contains personal context that shouldn't leak.

Write significant events, thoughts, decisions, opinions, lessons.
This is curated memory — the distilled essence, not raw logs.

One strong opinion from OpenClaw's docs: no mental notes. If the agent wants to remember something, it writes it to a file. "Mental notes don't survive session restarts. Files do." That applies equally well to coding agents.


Apply this: start the memory system before you need it

Most people set up OpenClaw's memory system after they wish they had it — after a session where the agent gave advice that contradicted something discussed two weeks ago. Start it on day one. Create memory/ and the daily log structure, add the memory rules to AGENTS.md, and let it accumulate. Memory systems compound; the later you start, the longer you wait for them to be useful.


TOOLS.md — environment-specific notes

Skills are shared and reusable. Your specific setup is not. TOOLS.md keeps them separate.

# TOOLS.md

### Cameras
- living-room → Main area, 180° wide angle
- front-door → Entrance, motion-triggered

### SSH
- home-server → 192.168.1.100, user: admin

### TTS
- Preferred voice: "Nova" (warm, slightly British)
- Default speaker: Kitchen HomePod

This separation is practical. You can update or share skills without leaking your infrastructure details. And your device names and SSH aliases do not clutter skill definitions that are meant to be generic.


The group chat context leak

MEMORY.md must only load in the main session (direct chat with the owner). If it loads in a Discord server or group WhatsApp, personal context — preferences, decisions, private notes — becomes visible to everyone in that channel. OpenClaw's default AGENTS.md enforces this boundary explicitly. Don't remove that check when customising your own AGENTS.md.


HEARTBEAT.md — proactive behaviour

Coding agents are reactive — they wait for you to ask something. OpenClaw agents can be proactive.

The gateway sends periodic heartbeat polls to the agent. When a heartbeat arrives, the agent reads HEARTBEAT.md and decides what to do:

# HEARTBEAT.md

Check:
- Emails: urgent unread messages?
- Calendar: events in next 24h?
- Mentions: Twitter/social notifications?
- Weather: relevant if human might go out?

The agent rotates through these checks 2-4 times per day, tracks what it last checked in memory/heartbeat-state.json, and only reaches out when something warrants it. Late night (23:00-08:00) stays quiet unless something is urgent.

OpenClaw also distinguishes heartbeats from cron jobs:

Mechanism When to use
Heartbeat Batch multiple checks together, timing can drift, needs conversational context
Cron Exact timing required, isolated from main session, one-shot reminders

Group chat behaviour

This is where OpenClaw's convention files diverge most from coding agents. A coding agent talks to one person in an editor. An OpenClaw agent might be in a Discord server with dozens of people.

OpenClaw's AGENTS.md has explicit rules:

Respond when:

  • Directly mentioned or asked a question
  • You can add genuine value
  • Something witty fits naturally
  • Correcting important misinformation

Stay silent when:

  • Casual banter between humans
  • Someone already answered the question
  • Your response would just be "yeah" or "nice"
  • The conversation flows fine without you

The guiding principle: "Humans in group chats don't respond to every single message. Neither should you. Quality over quantity."

There is also guidance on reactions (emoji reactions are lightweight social signals — use them like a human would) and a "triple-tap" warning: don't respond multiple times to the same message with different reactions.


How it compares to coding-agent files

Concern Coding agents OpenClaw
Identity Not needed — agent is a tool SOUL.md — agent has personality
Memory Git history, project files MEMORY.md + daily logs
Scope One repo, one session Multiple channels, always-on
Proactivity Reactive only Heartbeats and cron
Multi-user Single developer Group chats with strangers
Privacy Project-level (.gitignore) Session-level (main vs group)
Environment Editor context TOOLS.md (devices, SSH, voices)
Bootstrapping Not needed BOOTSTRAP.md (first-run)

The shared concept is the same: markdown files that define agent behaviour, loaded at predictable times, with clear ownership. The differences come from what the agent is doing — editing code vs living in your pocket.


What coding agents can learn

A few of OpenClaw's ideas port well to development workflows:

Memory as files, not context. The "no mental notes" rule matters for long coding sessions too. If an agent discovers something about your codebase, it should write it down — in a memory file, a comment, a doc — not hold it in context that disappears when the session ends.

Explicit safety defaults. OpenClaw's AGENTS.md starts with safety. Coding agents often rely on tool restrictions (.agent.md in VS Code) but rarely state behavioural safety rules as plainly as "Don't run destructive commands unless explicitly asked."

Heartbeat-style proactive checks. A CI/CD agent that periodically checks pipeline health, dependency vulnerabilities, or stale branches — without being asked — would be worth having.


Getting started with OpenClaw

  1. Install: npm install -g openclaw@latest
  2. Onboard: openclaw onboard --install-daemon
  3. Create your workspace: mkdir -p ~/.openclaw/workspace
  4. Copy the templates: AGENTS.md, SOUL.md, TOOLS.md
  5. Connect a channel (Telegram is fastest)
  6. Start chatting

The workspace is just a directory with markdown files. Back it up as a private git repo if you want version history on your agent's memory and personality.


Further reading


Frequently asked questions

How does OpenClaw handle privacy across multiple messaging channels?

OpenClaw enforces a session-type boundary: MEMORY.md (personal context) only loads in the main session — direct messages with the owner. In shared contexts like Discord servers or group chats, personal memory stays unread. The agent can still be helpful in group chats; it just works from the session context rather than your private notes. This boundary is defined in AGENTS.md and must be maintained when you customise it.

What's the difference between SOUL.md and AGENTS.md in OpenClaw?

AGENTS.md defines what the agent does — safety rules, session startup sequence, memory system, skill invocation. SOUL.md defines who the agent is — personality, tone, what it finds interesting, how it handles disagreement. A useful analogy: AGENTS.md is the job description; SOUL.md is the character. Both load on every session start. You need both.

Can SOUL.md be updated by the agent itself?

Yes — and this is intentional. OpenClaw's design allows the agent to update its own SOUL.md as its personality evolves, with the rule that it tells the owner when it does so. This gives the agent a mechanism for genuine development over time rather than being frozen at first-configuration personality. Back up SOUL.md periodically if you want to track how it changes.

How does HEARTBEAT.md differ from setting up cron jobs?

Heartbeats and cron jobs serve different purposes. HEARTBEAT.md is for batching multiple checks together in a conversational context — the agent reviews several things at once and reaches out only if something warrants it. Cron jobs are for exact-timing requirements and isolated, one-shot reminders. Use heartbeats for ambient monitoring (email, calendar, mentions); use cron for time-specific notifications ("remind me at 9am Monday").

What's the minimum OpenClaw setup to get value in the first week?

Install OpenClaw, write a brief SOUL.md with your communication preferences, set up one messaging channel (Telegram is fastest), and start a daily log in memory/. Skip HEARTBEAT.md and skills until the basics feel natural. The memory system alone — an agent that remembers what you discussed yesterday — delivers immediate value and requires almost no configuration beyond creating the memory/ directory.

Agentic policy management: Kyverno, MCP, and closed-loop multi-cluster governance

Banner image Banner image

Agentic policy management: Kyverno, MCP, and closed-loop multi-cluster governance

The Kyverno MCP and Kagent session at KubeCon EU 2026 was interesting for one reason above all others: it treated policy management as an operational workflow problem, not just a policy authoring problem.

Most teams already know how to write policies. The harder problem is running them across many clusters, proving they still work, troubleshooting interactions, and doing all of that without burning platform engineers on repetitive manual checks.

That is where the talk moved the conversation forward.

The visual map

Agentic policy governance loop Agentic policy governance loop


Measure operator effort, not just policy coverage

It's easy to count how many policies you have. It's harder — and more important — to measure how much manual work is required to validate and operate them across a multi-cluster fleet. That's the metric the Kyverno + Kagent session was really optimising for: reducing human overhead, not adding more policies.

The real bottleneck is operational overhead

The session described a familiar multi-cluster reality:

  • production and non-production clusters span regions and versions
  • policy state is spread across reports, logs, events, and ad hoc kubectl sessions
  • proving a policy is still effective often requires manual negative testing
  • troubleshooting policy interactions depends too heavily on senior-engineer memory

In other words, the policy engine is usually not the slowest part. The operator workflow is.

This is the same pattern we saw in other strong platform talks this year: the main scalability issue is often not the underlying runtime, but the human operating model wrapped around it.

What the architecture is really doing

The talk combined three layers.

1. Kyverno remains the enforcement and lifecycle engine

Kyverno is still the trusted policy foundation. That matters, because agentic automation is only useful if the underlying enforcement layer is deterministic and auditable.

The speakers positioned Kyverno as more than an admission controller. It now spans a broader policy lifecycle:

  • validation
  • mutation
  • generation
  • image verification
  • reporting
  • exemptions
  • cleanup and deletion workflows

That is an important framing shift. Governance is not just block-or-allow anymore. It is a full operational loop.

2. MCP and Kagent provide the action layer

The second layer is an agentic control surface that can translate a request like:

  • show me the latest policy violations on production clusters
  • install the relevant policies and give me the report
  • audit this cluster against Pod Security Standards

into actual cluster operations.

The point is not chat for its own sake. The point is compressing scattered, specialist operational steps into bounded workflows that can be run consistently.

3. Skills package institutional knowledge

The strongest idea in the session was the use of reusable policy skills.

This is how teams stop operational knowledge from being trapped in:

  • a senior engineer's head
  • old Slack threads
  • half-remembered runbooks
  • ten different docs pages

A skill becomes a reusable unit of governance behavior. It knows how to install Kyverno, run an audit, collect reports, or troubleshoot a class of problem. That is more valuable than a generic assistant because it turns policy operations into shareable platform capability.

Why this matters beyond Kyverno

This talk was nominally about Kyverno, MCP, and Kagent, but the pattern is bigger than the toolchain.

Platform teams increasingly need closed-loop operations:

  1. detect state
  2. compare it to intent
  3. take bounded action
  4. report what changed
  5. preserve auditability and approvals

That is the real architecture pattern here.

If you strip away the project names, the session was really about converting governance from manual inspection into productized operational flow.


An agent that can act across clusters is a privileged operator

The speakers were explicit: agentic policy tooling needs a stronger security model, not a weaker one. Isolation between execution contexts, strong identity and approval boundaries, network lockdown, trusted skill sources, and comprehensive audit trails are not optional extras — they're the table stakes for governing automation with cluster-level access.

The security warning was the right one

The speakers were careful not to oversell autonomy.

An agent that can act across clusters is not just another dashboard. It is a privileged operator. That means the security model has to be stronger, not weaker.

The talk highlighted the right controls:

  • isolation between execution contexts
  • strong identity and approval boundaries
  • network lockdown
  • trusted skill sources and supply chain controls
  • human approval for sensitive remote actions
  • comprehensive logging and audit trails

This is the same lesson showing up across the better AI-platform discussions at KubeCon: governed automation wins, not unconstrained automation.


Apply this: turn repeated governance tasks into reusable skills

If your team keeps repeating the same checks — policy audits, violation reports, remediation sequences — those are candidates for skills. A skill that knows how to audit a cluster against Pod Security Standards is more valuable than a generic assistant, because it turns operational knowledge into shareable platform capability instead of leaving it in someone's head.

What platform teams should do with this now

If you manage policy across multiple clusters, there are four practical takeaways.

1. Measure operator effort, not just policy coverage

It is easy to count the number of policies. It is harder, and more important, to measure how much manual work is required to validate and operate them.

2. Turn repeated governance tasks into reusable workflows

If your team keeps repeating the same checks, audits, and remediation steps, those are candidates for skills, automation, or both.

3. Keep enforcement deterministic, make operations smarter

The right split is simple:

  • deterministic policy engine underneath
  • bounded intelligent orchestration above it

Do not reverse that order.

4. Treat agentic governance as privileged infrastructure

If an agent can read state, change policy, install tooling, or act across clusters, it belongs inside the same trust and audit model as other high-privilege operational systems.

The broader KubeCon pattern

This session fit neatly into the wider event theme.

The strongest KubeCon talks this year were all about reducing platform friction without giving up control:

  • Backstage becoming a multi-surface operating layer
  • TAG DevEx focusing on measurable, scoped friction reduction
  • self-service environment platforms killing ticket queues with policy guardrails
  • Kyverno and Kagent moving governance toward closed-loop execution

That is the pattern worth paying attention to. Platform engineering is becoming less about exposing raw infrastructure and more about packaging safe operational behavior.


Frequently asked questions

What is Kagent and how does it relate to Kyverno?

Kagent is an agentic orchestration layer for Kubernetes operations. It works alongside Kyverno (the policy engine) rather than replacing it — Kyverno handles deterministic enforcement, Kagent handles the operational workflow around it: running audits, collecting reports, triggering remediations, and surfacing results. Think of it as the control surface above the policy engine.

Do Kyverno skills require a specific agent framework?

No — skills in the Kyverno context follow the open SKILL.md standard. They're markdown files that define reusable operational procedures any compliant agent can follow. You can use them with Claude Code, VS Code Copilot, or any agent that supports the SKILL.md spec. The skill defines the what; the agent runtime determines the how.

How do you audit policy coverage across 20+ clusters without doing it manually?

That's exactly what the agentic workflow is for. The MCP layer translates "audit these clusters against Pod Security Standards" into a sequence of cluster operations — connecting to each cluster, running the relevant Kyverno checks, collecting policy reports — then aggregates the results. What previously required a senior engineer running commands against each cluster becomes a single agent invocation.

What's the right split between deterministic policy enforcement and agent-assisted governance?

Keep enforcement deterministic: Kyverno admission control is the source of truth for allow/deny decisions, always. Agent assistance lives above that layer — pre-flight checks, post-incident diagnosis, periodic audits, remediation suggestions. Never let an agent bypass or override the admission controller. Governed automation above, deterministic enforcement below.

Can Kyverno policies be managed via GitOps alongside agent-assisted operations?

Yes, and this is the recommended pattern. Policy manifests live in Git and are deployed via ArgoCD or Flux — the GitOps workflow handles policy lifecycle. Agent workflows handle the operational layer: testing policies, collecting violation reports, diagnosing issues. The two layers are complementary: GitOps for policy state management, agents for operational intelligence.


References

AI governance for platform teams: Agents in production without losing control

Banner image Banner image

AI governance for platform teams: Agents in production without losing control

One of the recurring tensions at KubeCon EU 2026 was this: AI agents are powerful for dramatic cost reductions and faster response to incidents, but deploying them without governance is how you end up with a $500k surprise bill or a cascade of auto-scaled clusters that don't stop.

The strongest talks—especially RBI's work on moving from GitOps to AIOps and the broader keynote discussions on AI's role in platform engineering—showed a clear pattern: the question is not "should we use AI agents?" but "how do we make agents safe enough to trust with infrastructure?"

Quick takeaways

  • Agents need hard boundaries: Not all decisions can be autonomous; infrastructure agents need to know exactly what decisions they can make (resource scaling, failure recovery, cost optimisation) versus what requires human review (risk-tier changes, major architectural decisions, compliance modifications)
  • Observability is the foundation for trust: You cannot safely grant autonomy without visibility into exactly what an agent did, why, and what constraints it considered; this is non-negotiable for regulated environments
  • Review workflows are governance: Adding a "human reviews major decisions" layer is not a bug or overhead—it's the core governance mechanism that makes AI-assisted operations work in production
  • Agents should be organisationally aware: The best AI systems understand your risk model, cost allocation, and team structure; generic agents fail because they don't know what "reasonable" looks like in your context

AI governance decision flow AI governance decision flow


AI governance must be architectural, not procedural

Procedural governance — "always get approval before changing production" — relies on humans remembering to follow the process under pressure. Architectural governance — encoding decision tiers, approval gates, and cost limits directly into the system — enforces the process automatically. RBI's approach works because the constraints are in the platform, not in a policy document.

What was getting in the way

Prior to KubeCon, organisations deploying AI agents ran into a hard set of problems:

  1. All-or-nothing autonomy — Either the agent is fully autonomous (risky) or fully manual (defeats the purpose). Few organisations had a clear middle ground
  2. Observability gaps — When an AI system makes a decision, logs often don't explain why, making it hard to detect errors or audit for compliance
  3. Context collapse — The AI system doesn't understand your risk model. It sees "this service needs more resources" and scales it without understanding if it's a pre-production test environment or a critical revenue system
  4. Governance bolted on after the fact — Organisations added approval workflows after agents were already making mistakes, leading to reactive restrictions rather than thoughtful design

RBI's approach (detailed in From GitOps to AIOps in regulated environments) solved this with a clear architecture: - AI acts as a second pair of eyes during change reviews, not as an autonomous actor - Every infrastructure change goes through a risk-aware promotion pipeline - AI provides insights (cost estimates, failure predictions, blast radius analysis) to the human reviewer, who retains final say - The system is observable: you can trace exactly what information the AI considered and what recommendation it made

This is not AI doing less work; it's AI doing different work: intelligence rather than autonomy.

The three layers of AI governance

Layer 1: Bounded decision contexts

Not all infrastructure decisions are equal. A production agent should be able to: - Scale resource requests up or down (within bounds) - Retry failed operations with exponential backoff - Diagnose routine failures (pod crashes, network timeouts, dependency issues) - Optimize resource utilisation (consolidate workloads, shed low-priority batch jobs)

But should require human review for: - Changes to risk tier or compliance classification - Shifts between infrastructure providers (AWS → Azure) - Modifications to network boundaries or security zones - Cost optimizations that require architectural change - Decisions that affect billing or quota allocations

Example boundary definition:

Tier 1 (Fully Autonomous):
  - Scaling within ±50% of baseline resources
  - Restarting failed services
  - Adjusting monitoring thresholds
  - Optimizing pod scheduling

Tier 2 (AI Recommendation + Human Review):
  - Scaling beyond 50% baseline (suggests reason; human approves)
  - Changing infrastructure provider (AI outlines cost/risk tradeoff; human decides)
  - Modifying security group rules (AI explains the request; human validates)
  - Cross-cluster workload migration (AI recommends based on cost; human decides)

Tier 3 (Fully Manual):
  - Risk tier promotion (dev → staging → production)
  - Compliance policy changes
  - Architecture refactoring
  - Disaster recovery activation

The key is that the boundaries are explicit and encoded in the system, not left to human judgment in the moment.


All-or-nothing autonomy is the failure mode

Either the agent is fully autonomous (risky) or fully manual (defeats the purpose). The teams that got this wrong added approval workflows reactively — after agents were already making mistakes — which created resentment rather than trust. Design the tier boundaries before deploying agents, not after the first incident.

Layer 2: Observability as governance

The best AI governance mechanism is seeing exactly what the agent did and why.

Crossplane v2 (covered separately in Crossplane v2: API-first platforms and compositional control planes) enables this with rich status conditions and event streams. When applied to AI-augmented operations, this means:

Every agent decision includes: - What it was asked to do — "Diagnose why this service is slow" - What it observed — "62% CPU, 4.2s p99 latency, 30% memory utilisation" - What constraints it knew — "This is staging, so cost optimisation takes precedence" - What it decided — "Recommend increasing CPU allocation from 500m to 1000m" - What it didn't do and why — "Did not recommend increasing memory (not the bottleneck); did not recommend autoscaling (staging use is predictable)" - Confidence level — "High confidence (prior similar cases: 47/51 correct)" - Timestamp and context — "2026-03-25 14:23:41 UTC, requested by on-call automation"

This information flow is what enables the human reviewer to: - Verify the AI reasoning is sound - Spot cases where the AI misunderstood the context - Build confidence that the system is safe to trust more autonomously - Audit for compliance or incident post-mortems

Operationally, this looks like:

# AI observation record
apiVersion: ai.platform.example.com/v1
kind: AgentDecision
metadata:
  name: scale-api-service-2026-03-25-14-23-41
  namespace: platform-ai
spec:
  decision_type: resource_scaling
  service: api-search
  environment: staging
  timestamp: "2026-03-25T14:23:41Z"
  context:
    cpu_utilisation: 62
    memory_utilisation: 30
    p99_latency_ms: 4200
    error_rate: 0.001
    cost_tier: staging-optimised
status:
  action: ScalingRecommended
  current_cpu_request: "500m"
  recommended_cpu_request: "1000m"
  confidence: 0.92
  reasoning: "CPU contention correlates with latency spike; memory is not a bottleneck"
  approved: true
  approved_by: on-call-automation
  approved_at: "2026-03-25T14:23:55Z"
  executed_at: "2026-03-25T14:24:02Z"
  events:
  - timestamp: "2026-03-25T14:23:41Z"
    type: ObservationComplete
    message: "Collected metrics from 89 pods over 5 minutes"
  - timestamp: "2026-03-25T14:23:50Z"
    type: RecommendationGenerated
    message: "Generated scaling recommendation based on CPU analysis"
  - timestamp: "2026-03-25T14:23:55Z"
    type: ReviewedAndApproved
    message: "Approved by on-call automation (within bounded tier)"
  - timestamp: "2026-03-25T14:24:02Z"
    type: ExecutionComplete
    message: "Updated CPU request in Deployment spec"

With this level of transparency, platform teams can: - Automatically approve routine decisions - Alert on decisions that look suspicious (high confidence but unusual reasoning) - Train the AI system (log unusual cases for model refinement) - Satisfy compliance audits (full decision trail with reasoning)

Layer 3: Organisational alignment

The AI system needs to understand your organisational context: risk models, cost models, team structure, and strategic priorities.

RBI example (regulated banking): - High-cost risk tier: "This change affects core banking systems; requires multi-layer approval" - Medium-cost risk tier: "This change is isolated to a cluster or namespace; can proceed with on-call review" - Low-cost risk tier: "This change is ephemeral (testing, dev); autonomous operation within cost limits"

Sony example (platform product): - Producer team decision: "My team owns this infrastructure; I can make scaling decisions autonomously" - Consumer team decision: "This is provided infrastructure; I can ask for scaling but not make decisions" - Cost-sensitive environment: "Optimise for utilisation first; only auto-scale if utilisation >80%"

The AI needs to know:

# Organisational context for AI
apiVersion: governance.platform.example.com/v1
kind: InsecurityModel
metadata:
  name: production-ai-governance
spec:
  riskTiers:
    - name: production-banking
      level: critical
      autonomousActions: []  # No autonomous actions in banking systems
      requireApproval: true
      approverGroups: [security-team, on-call-lead]
      maxAutoScalingFactor: 1.2  # Max 20% increase without approval
      costThresholdPerHour: 500  # Alert if hourly cost would exceed $500

    - name: production-services
      level: high
      autonomousActions:
        - restart-failed-services
        - scale-within-50-percent
        - optimize-scheduling
      requireApproval: false
      autorollbackOnError: true
      costThresholdPerHour: 1000

    - name: staging
      level: medium
      autonomousActions:
        - all-scaling
        - all-optimization
        - cost-driven-consolidation
      requireApproval: false
      costThresholdPerHour: 500  # Auto-stop if exceeding $500/hr

    - name: development
      level: low
      autonomousActions: [all]  # Minimal constraints; cost + safety only
      costThresholdPerHour: 200  # Hard limit at $200/hr

With this context, the AI system can reason: "This is a production banking system, so I should not auto-scale it; I will generate a detailed recommendation for the on-call lead instead."

Pattern matching: AI review layers

The pattern that emerged from KubeCon talks (especially RBI) is that AI does best work when positioned as a review layer, not an execution layer.

Traditional GitOps pipeline:

Code PR → CI Tests → CD Pipeline → Deployed

AI-augmented pipeline (RBI pattern):

Code PR → CI Tests → AI Review → CD Pipeline → Deployed  →  Runtime AI (AIOps)
                     ↓
              [Explains risks, cost,
               prior failure patterns,
               dependency impacts]

In this role: - AI explains risks in human terms ("This change affects 40 services downstream; 3 have had incidents in the past month") - AI suggests rollback strategies ("If this fails, consider rolling back in this order") - AI validates constraints ("This change respects all required SLOs and cost limits") - Human approves with confidence and context

At runtime (AIOps):

Metric Spike → Runtime AI → Issue Diagnosis → Recommendation → Approval → Action
              [< 100ms]   [< 1s]             [< 10s]          [Varies]   [Exec]

AI diagnoses issues at machine speed, but human approval remains the gate before execution.


Apply this: start with AI as a review layer, not an execution layer

Position AI to explain risks, surface prior failure patterns, and estimate blast radius for human reviewers. Let humans approve. Earn trust through transparency. Expand autonomy incrementally as the track record builds. "AI as second pair of eyes" is not a compromise — it's the production-grade pattern for regulated and high-stakes environments.

Practical action items

  1. Define your decision tiers explicitly — What decisions are autonomous, what requires review, what is never automated? Document this as policy before deploying agents
  2. Implement observability first — Before granting any autonomy, ensure you can trace every agent decision. This is your audit trail and your safety mechanism
  3. Start with review workflows, not autonomous execution — Position AI as a recommendation engine that humans review and approve. You can expand autonomy later once trust is built
  4. Encode organisational context — Your AI needs to know about risk tiers, cost models, and team structure. Generic agents will fail
  5. Use bounded contexts for autonomous decisions — Resource scaling within 50% of baseline is safer than scaling unbounded
  6. Monitor AI reasoning quality — Log cases where the AI makes suggestions that are wrong. Use these to refine the system
  7. Set hard cost limits — Autonomous cost optimisation can go wrong fast; put caps in place (e.g., "no single decision costs more than $X")
  8. Build approval workflows with AI hints — The review process should be fast (< 1 minute) but thorough; AI provides context so humans can decide quickly
  9. Test failure modes deliberately — What happens if the AI system is wrong? Can you automatically rollback? How will you detect the problem?
  10. Plan for opacity and interpretability — As AI systems get more complex, some decisions will be hard to explain. Decide in advance which decisions require interpretability vs. which can be trusted based on outcomes

Scaling governance: from bounded agents to governed platforms

The picture that emerged across RBI, Sony, and the keynotes is this: you don't scale by making agents more autonomous; you scale by making governance more sophisticated.

The goal is not "fully autonomous AI systems managing infrastructure" but rather "humans and AI systems cooperating in ways that are safe, auditable, and aligned with business constraints."

RBI's approach—AI as a second pair of eyes reviewing changes—is not a compromise. It's the actual production-grade pattern: fast, safe, auditable, and aligned with how regulated environments work anyway.

This ties directly into platform teams being product teams (see Platform teams are product teams): the "product" your platform offers to application teams includes not just infrastructure APIs but also governance built into those APIs.


Frequently asked questions

How do you define the tier boundaries for autonomous vs human-reviewed decisions?

Start with blast radius and reversibility. Tier 1 (fully autonomous): fast to reverse, affects one service, within-baseline resource changes. Tier 2 (AI recommendation + human review): cross-service impact, provider changes, security group modifications. Tier 3 (fully manual): compliance changes, disaster recovery, architectural refactoring. Make the boundaries explicit in a CRD or config, not in a runbook.

What does 'observability as governance' mean in practice?

Every agent decision includes: what it was asked to do, what it observed, what constraints it knew, what it decided, what it didn't do and why, and its confidence level. This structured decision record lets humans verify reasoning, detect systematic errors, satisfy compliance audits, and build trust incrementally. Without it, autonomous decisions are a black box — and black boxes don't get trusted with production infrastructure.

How do you handle agents that operate across multiple clusters with different risk tiers?

Encode the risk tier in the cluster registry labels (e.g. risk-tier: production-banking, risk-tier: staging). The governance CRD maps risk tiers to allowed autonomous actions, approval requirements, and cost thresholds. The agent reads the tier from cluster metadata before deciding which action class applies. RBI's approach is the reference implementation for this pattern.

What's the right cost cap for autonomous agent decisions?

There's no universal number, but the principle is: set a per-decision cost threshold below which the agent acts autonomously, and above which it requires human approval. For most platform teams, something like "any single autonomous decision that would increase hourly infrastructure cost by more than $X requires review" is a reasonable starting point. Tune X based on your cloud bill's tolerance for surprises.

How do you build trust in an AI governance system incrementally?

Start with read-only operations (diagnosis, analysis, recommendations). Log every decision with full reasoning. Run the system in "shadow mode" — generate recommendations but don't act on them — and verify they would have been correct. Gradually expand to low-blast-radius autonomous actions as the track record builds. Track the false positive and false negative rate explicitly. Trust is earned through a visible track record, not assumed from day one.

See also: - From GitOps to AIOps in regulated environments — RBI's specific architecture and decision patterns - Crossplane v2: API-first platforms and compositional control planes — How control planes provide the foundation for governed autonomy - KubeCon EU 2026: what actually mattered — Broader context on AI governance themes from keynotes - KubeCon EU 2026 event notes — Full conference coverage